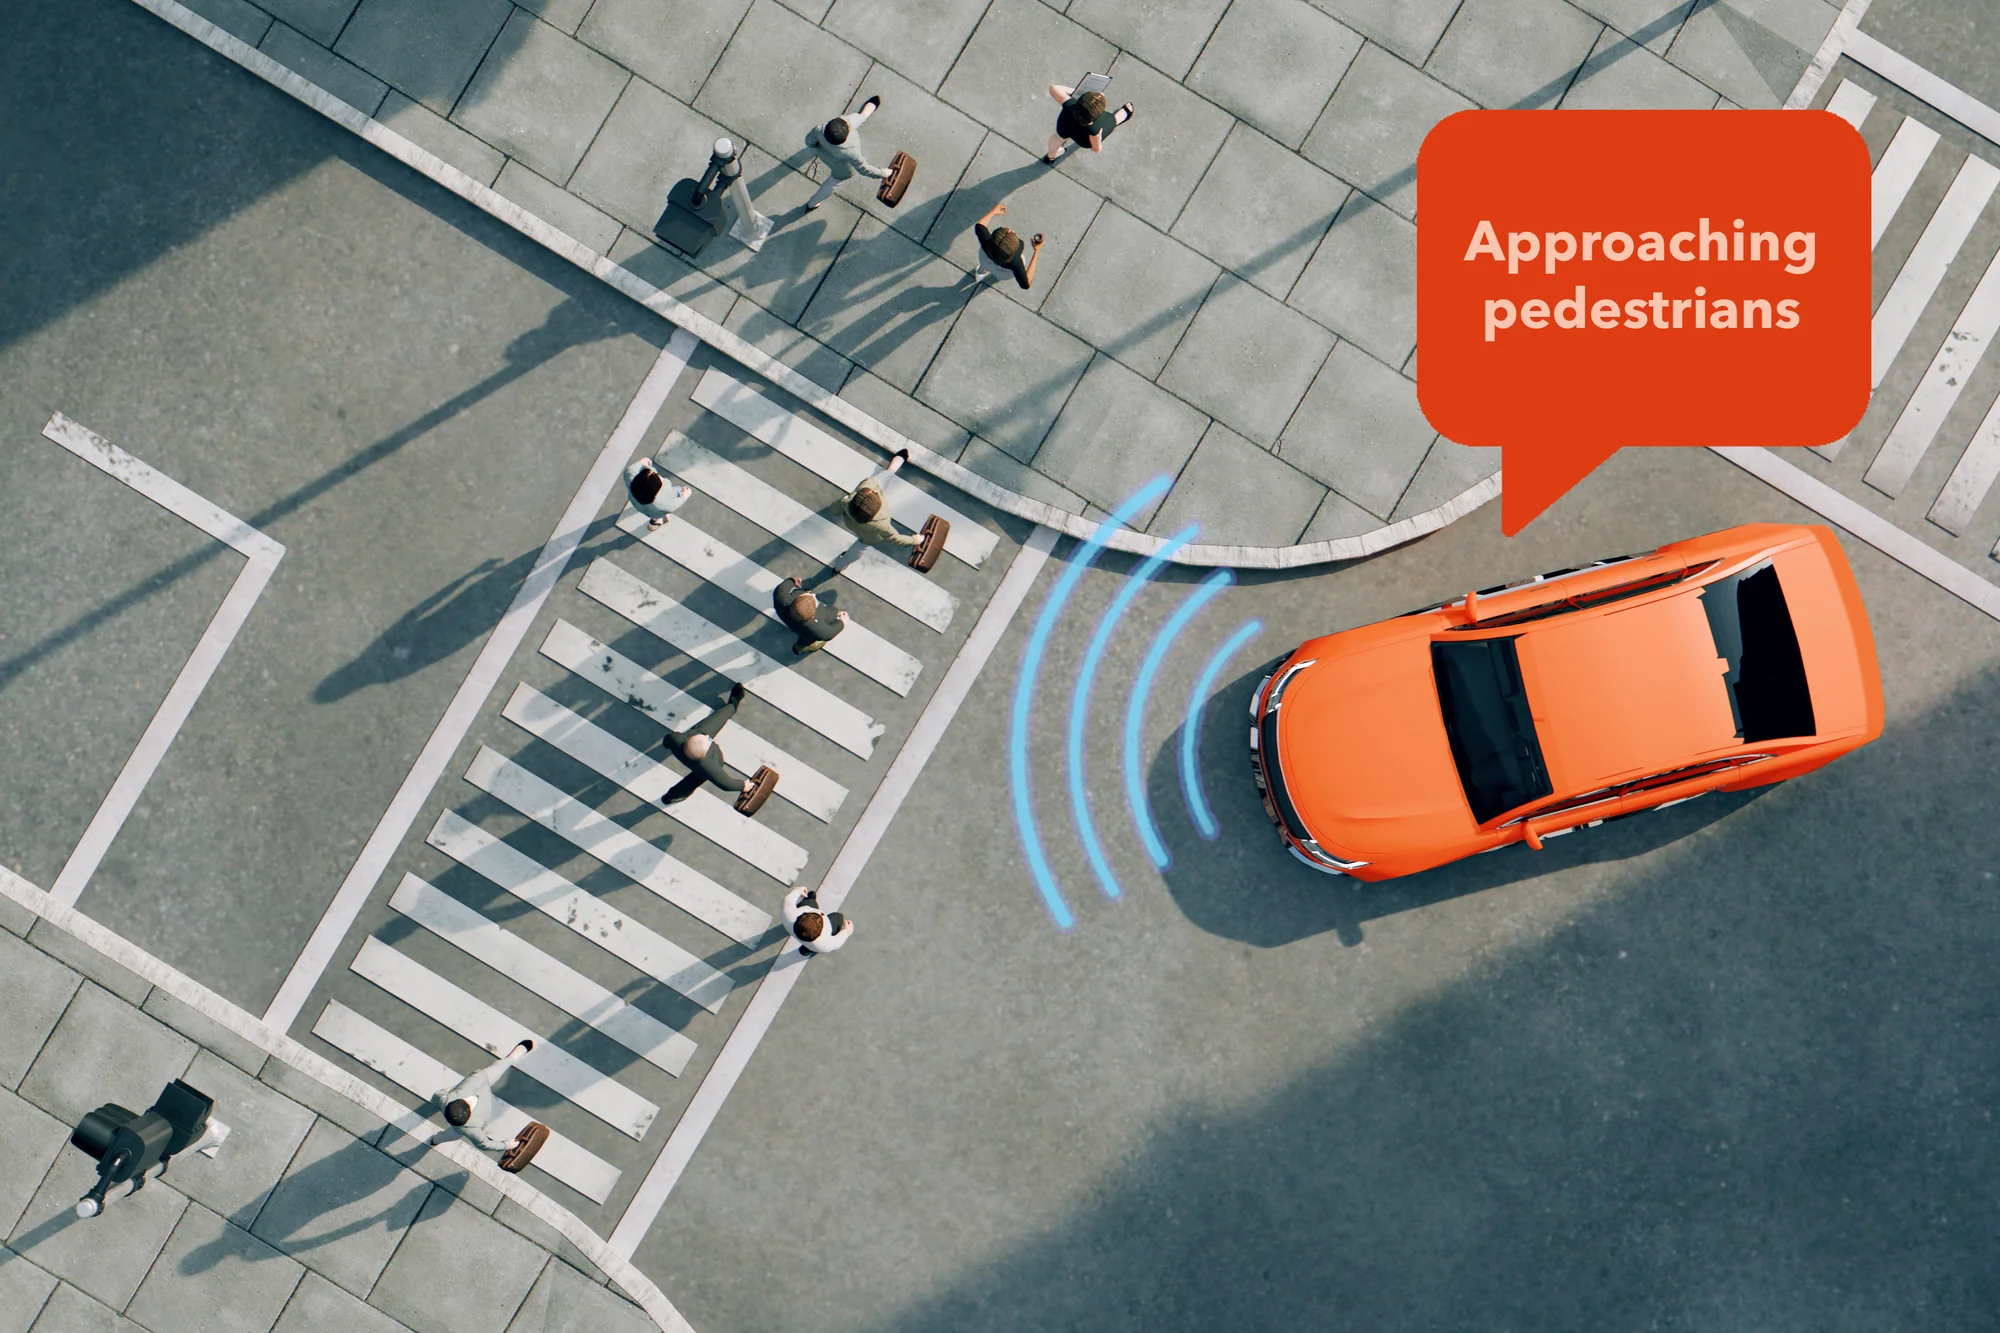
CW-Net explains self-driving planners in real time with causally faithful concepts
MIT and Motional introduce Concept-Wrapper Network (CW-Net), a module inserted into machine-learning planners that classifies driving scenes into human-understandable concepts and forces subsequent trajectory decisions to use them, yielding real-time, causally faithful explanations. Tests with a Motional robotaxi on a private track and with nonexpert users in simulations improved predictions of vehicle behavior; the work appears in Nature.
The reported event is the introduction of CW-Net, a concept-wrapper network developed by researchers from MIT and autonomous driving company Motional. It produces explanations for a self-driving vehicle's planning model using human-understandable concepts such as 'approaching stopped vehicle' and 'close to cyclist', generated in real time alongside the output trajectory.1
Context
The method addresses a known bottleneck in autonomous driving: the deep-learning planners that act as the vehicle's 'brain' process camera and lidar data into a high-level environment summary and decide a trajectory, but their internal reasoning is opaque, leaving drivers and engineers unable to explain events such as phantom braking. CW-Net is a concept classifier inserted into the middle of the existing planner; it translates the internal reasoning into understandable concepts and forces the final trajectory component to use those concepts when deciding what to do next.1
Assessment
The evidence reported consists of two tests. CW-Net was installed in a Motional robotaxi on a private track with a safety driver, and larger online simulation studies used real driving situations from Las Vegas; in both, CW-Net explanations improved people's ability to predict how the autonomous vehicle would behave. In the private-track case, CW-Net revealed that the model was not properly configured to detect a cyclist and had stopped because its emergency braking procedure triggered, correcting the safety driver's false assumption that the stop was a normal cyclist response.1
Caveats
The study should be treated cautiously because the public account is a single-source announcement of a Nature paper; it gives qualitative findings and one illustrative failure mode, not effect sizes, quantitative baselines, or detailed failure analysis. What would most quickly change my assessment would be access to those quantitative results, evidence that the wrapped planner remains behaviorally equivalent across more than the observed scenarios, and a demonstration that the concept vocabulary scales beyond the 130 million examples already used for training.1
Self-driving cars are often controlled by deep learning models that sometimes fail in unexpected situations. For instance, the car might inexplicably brake and block the path of an oncoming emergency vehicle. A human driver or passenger may need to react rapidly to prevent a collision.
To help humans better anticipate a vehicle’s mistakes, researchers from MIT and autonomous vehicle technology company Motional developed a new method that provides clear explanations of the underlying model’s decisions.
Usually, the internal reasoning process of a deep learning model is opaque and difficult to understand. But the new method, called the Concept-Wrapper Network (CW-Net), translates that reasoning process into concepts that faithfully describe the autonomous vehicle’s decisions without altering its driving performance.
CW-Net explains the decisions of machine learning-based planners using understandable concepts, like “approaching stopped vehicle” or “close to cyclist.” These explanations can correct misconceptions drivers and passengers have about vehicle behavior and improve their situational awareness.
In road tests on a private track, CW-Net explanations helped safety drivers more accurately predict vehicle behavior; a larger simulation study with nonexpert users yielded similar results. These experiments show how CW-Net can provide important feedback for engineers as they troubleshoot in-vehicle artificial intelligence systems. In the longer term, this technique could boost the safety and transparency of autonomous vehicles, while building appropriate trust in drivers and passengers.
“This work shows how explanations are supportive to the human’s mental model and understanding of the behavior of a system, and how it could be used in engineering and development to improve the technology,” says Julie Shah, an MIT professor of aeronautics and astronautics, director of the Interactive Robotics Group in the Computer Science and Artificial Intelligence Laboratory (CSAIL), and co-senior author of the paper on CW-Net. “Unless we are building these technologies in a way that we can rely on and predict their behavior, then it is a shaky and unsafe foundation for their use.”
She is joined on the paper by lead author Eoin Kenny, a former MIT postdoc who is now a senior AI researcher at J.P. Morgan Chase; co-senior author Momchil Tomov, a staff research scientist at Motional; as well as Motional team members Akshay Dharmavaram, Sang Uk Lee, Tung Phan-Minh, Shreyas Rajesh, Yunqing Hu, and Laura Major, president and CEO of Motional. The research appears today in Nature.
Faithful explanations
Machine-learning-based planners act as the “brain” of a self-driving car. These powerful deep-learning architectures process data from the vehicle’s cameras and lidar sensors, generate a high-level summary of the vehicle’s environment, decide what the car should do next, and output a trajectory for it to follow.
The planners are usually black-box models, which means their internal decision-making process is so complex it is difficult to understand. This can leave scientists and safety drivers in the dark about why an autonomous vehicle made an unexpected decision, like phantom braking.
The researchers designed CW-Net to explain a vehicle’s decisions using understandable concepts, while ensuring those explanations accurately reflect the true reasons behind its behavior.
“Especially in high-stakes settings like self-driving cars, it’s important that the explanations are not potentially misleading. Because CW-Net is causally faithful in how it makes decisions, that provides certain guarantees around the explanations,” Kenny says.
CW-Net is a “concept classifier,” an AI algorithm that has been trained to predict the high-level concepts that exist within input data. The researchers plug the CW-Net module into the middle of an autonomous vehicle’s existing machine-learning planner architecture.
It translates the model’s internal reasoning process into understandable concepts, like “approaching stopped vehicle” or “close to cyclist.” Then it forces the final piece of the planning model architecture to use those concepts when it decides what the vehicle should do next. In this way, CW-Net ensures the concepts faithfully explain the vehicle’s actions.
At the same time, CW-Net uses the concepts it classified to generate clear explanations that are output along with the vehicle trajectory, in real-time.
“Instead of just wondering why the car stopped, having real-time data provides feedback that lets you test the system during deployment. You could also give that data to an engineer to potentially improve the system,” Kenny says.
The researchers trained CW-Net to predict concepts using a dataset of 130 million examples of scenes from self-driving cars, with multiple labeled concepts in each scene. Using such a large, labeled dataset enables it to identify concepts accurately in a wide range of settings.
They also designed CW-Net to mimic the driving decisions of machine-learning-based planners, so the module would not negatively impact vehicle performance.
In the end, CW-Net generates accurate, understandable explanations without altering the original deep learning model.
Improving situational awareness
To test CW-Net, the researchers deployed the module on a real autonomous driving test vehicle (a Motional robotaxi) on a private track with a safety driver. They found that CW-Net helped the safety driver better predict how the vehicle would behave in surprising situations.
For instance, the vehicle consistently stopped when it approached a cyclist, and the safety driver assumed it did so because it detected that cyclist. But CW-Net explanations revealed that the model wasn’t properly configured to detect the cyclist and chose a trajectory that would have caused a collision. Instead, it stopped because its emergency braking procedure kicked in when it got too close.
Armed with this information about the model’s mistake, the safety driver could reduce speed or engage manual driving mode sooner in similar situations. This could also help engineers fix the model to avoid this failure in the future.
In larger online simulation studies using real driving situations captured on the roads of Las Vegas, the researchers saw similar results. CW-Net explanations significantly improved participants’ abilities to predict how an autonomous vehicle will behave.
In the future, the researchers could extend CW-Net so the module can cover more concepts and explore different training and design techniques that could boost performance and improve interpretability.
“Our study shows how crucial interpretability can be to these high-stakes environments, and how it should be on the mind of people as they are making AI in the future, for self-driving cars or other safety-critical environments,” Kenny says.
The source text above remains the property of its publisher and is reproduced for commentary.