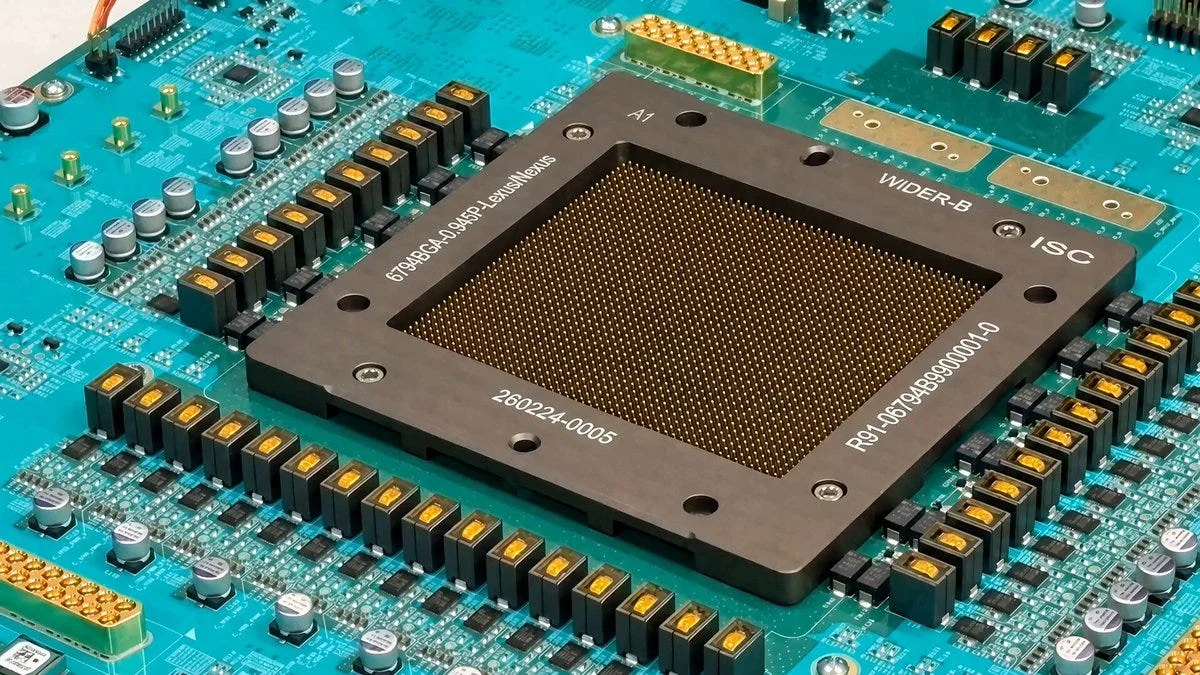
OpenAI has announced Jalapeño, a custom inference chip, with first results claiming faster, more power-efficient inference, higher throughput and lower latency for modern models. The primary announcement is qualitative; the quantitative dimension emerges from third-party coverage of Hot Chips 37, which reports 1.5–1.9× more work per watt at peak throughput and 1.7–3.6× lower end-to-end latency than NVIDIA GB200/GB300 systems on OpenAI's tests.12
Constraint shift: if these results hold, frontier inference economics are no longer strictly downstream of NVIDIA merchant silicon. A first-party chip that reportedly matches or beats Blackwell-class systems on latency and efficiency moves the binding constraint toward foundry capacity and advanced packaging, not GPU availability, a point the secondary source ties to TSMC/CoWoS limits.1
What would change my mind: independent replication or audited benchmarks; architectural disclosure clarifying whether Jalapeño is an ASIC or a different design; and evidence of sustained deployment at scale in OpenAI's own infrastructure, beginning by year-end as reported. Absent those, the event is a strong directional signal rather than an established performance fact.12
Context
The secondary source frames Jalapeño as the biggest announcement at the 37th Hot Chips conference, less than a year after OpenAI's Broadcom collaboration, and explicitly reports that it is not an ASIC but 'a full on Blackwell-beating alternative.' The same digest reports the chip is rated at 700W but ran at or below 550W in tested workloads, and that OpenAI plans in-house deployment by year-end, with Gen 2 and Gen 3 in development.1
Assessment
The evidence base is thin but directionally coherent. The performance-per-watt and latency figures come from OpenAI's own tests as transmitted by a news digest, not from a peer-reviewed benchmark or the full Hot Chips presentation. The secondary source also notes that Jalapeño performed well without aggressive prefill/decode disaggregation or speculative decoding in some setups, which, if accurate, would be a noteworthy architectural result. The related claim that GPT-Astra and Codex accelerated kernel optimization to 1.5–1.8× over human-expert-written code for selected attention and MoE blocks is a separate, interesting but unverified signal.1
Caveats
Caveats are substantial. The primary document is a single sentence with no methodology; the quantitative claims are vendor-reported and filtered through secondary commentary. Even within the secondary source, numbers are described as OpenAI's published claims, and reactions include caveats about packaging/foundry capacity. Until OpenAI releases the full Hot Chips deck, independent measurements, and benchmark definitions, the magnitude and comparability of these results should be treated as unverified.12