Hugging Face Releases Versioned WebGPU Kernel Packages, JS Loader, and Fleet Benchmarking
Hugging Face announced @huggingface/kernels, a JavaScript loader for running Hub-published WebGPU kernels, an initial collection of 207 versioned kernel repositories, and Fleet, a browser-based benchmarking suite. The post reports large per-operation speedups versus ONNX Runtime Web on a single Apple M4 GPU, with limitations in filtering, scope, and external validation.
Hugging Face has released @huggingface/kernels, a JavaScript loader for executing WebGPU kernels fetched from the Hub, together with an initial collection of 207 kernels published as versioned repositories under the webgpu-kernels organization. The same announcement introduces Fleet, a browser-based benchmarking suite that crowdsources correctness and performance evidence from user devices. The kernels and Fleet are positioned as the foundational operation layer for a faster browser-inference stack.1
Context
The collection covers operations used across machine-learning workloads, including matrix multiplication, normalization, attention primitives, quantization, and data-layout transformations. Each kernel repository includes an interface manifest, correctness tests, benchmark cases, provenance metadata, and parameterized WGSL shader templates. This packaging separates the operation contract from any single runtime and lets a loader select an implementation that fits the call and device.1
Assessment
The central new claim is that the vectorized, broadcasted, and scalar variants inside each kernel repository produce large speedups against ONNX Runtime Web. On an Apple M4 GPU, the authors report a 2.57x geometric-mean and 1.90x median speedup across 809 retained test cases, with 629 wins and 176 losses; selected pathological cases are up to four orders of magnitude faster. If independently reproduced, this would strengthen the case that WebGPU inference can be materially improved by replacing general shader implementations with shape- and device-aware variants rather than by only optimizing model-level orchestration.1
Caveats
The benchmarks are self-reported, cover a single GPU, are filtered to cases with matching outputs and reliable timings, and time only GPU work after excluding shader compilation, session creation, and data upload. The reported speedups are per-operation rather than for end-to-end models and do not generalize without Fleet-style evidence over more hardware and browsers. The Fleet privacy design has not yet produced public results; a change of mind would require independent replication, broad hardware coverage, and evidence that the kernels upstream into ONNX Runtime Web.1
Today, we are releasing the first layer of that effort: @huggingface/kernels , a minimal library for loading and running optimized WebGPU kernels from the Hugging Face Hub, together with an initial collection of 207 kernels at huggingface.co/webgpu-kernels.
The collection covers operations used across a wide variety of machine learning architectures and workloads. More importantly, each kernel is published as a complete, versioned package: its interface, shader templates, correctness cases, benchmark cases, and usage instructions all live together on the Hub.
We are also launching Fleet, an in-browser GPU benchmarking and testing suite that runs and scores the kernels on your hardware. Beyond the results for your own machine, Fleet gives the community a way to contribute performance and correctness evidence from devices we could never cover in a conventional test lab. With your consent, every run adds private evidence that can help us find failures (incorrect results, pathologically slow cases, etc.), improve kernel variants, and make better optimization decisions across real-world hardware.
207 WebGPU kernels, published as individual repositories in the webgpu-kernels organization. Apache-2.0 licensed.
A JavaScript loader, @huggingface/kernels , which downloads, prepares, and runs kernels directly from the Hub.
Explicit contracts and reproducible evidence for every kernel, including manifests, correctness tests, benchmark cases, and WGSL shader templates.
Fleet, a browser-based benchmarking tool that crowdsources correctness and performance evidence across real-world GPUs to help us improve kernels and their variants.
A model running in the browser eventually becomes a sequence of GPU operations: matrix multiplications, normalizations, convolutions, attention primitives, quantization operations, data-layout transformations, and many more. WebGPU makes these operations available across modern browsers through a portable API, while WGSL provides a common language for the shaders that execute them.
Portability, however, does not automatically mean performance. Two shaders can implement the same operation and produce the same output while behaving completely differently across different accelerators. Workgroup sizes, memory access patterns, vectorization, data types, and fusion strategies can all affect performance. The best choice can also change with the input shape, device, browser, and available WebGPU features.
This is why kernels form a foundational layer of fast browser inference. Higher-level runtimes can only be as efficient as the operations they dispatch. By making those operations individually discoverable, testable, benchmarkable, and versioned, we can improve the foundation independently while keeping a stable contract for the layers above it.
Each kernel in the collection has its own repository and kernel card. The card documents the operation's semantics, inputs, outputs, attributes, supported data types, source files, and a ready-to-run @huggingface/kernels example.
For example, ai.onnx.Add implements elementwise addition with multidirectional broadcasting. It is one of the simplest operations in a neural network, used everywhere from residual connections to adding a bias. Its card documents the two inputs, the broadcasted output shape, supported data types, and the variants available for different shapes and devices.
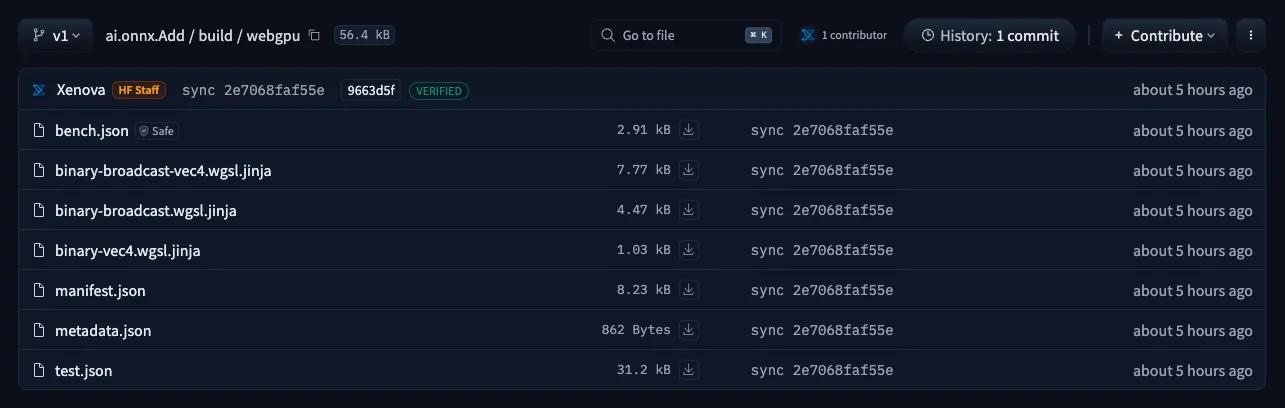
The ai.onnx.Add repository packages its manifest, correctness and benchmark cases, and WGSL shader templates together.
ai.onnx.Add
Behind the card, the repository contains the artifacts needed to understand and evaluate the implementation:
manifest.json is the source of truth for the operation contract. It defines inputs, outputs, attributes, type constraints, and shape derivation rules.
metadata.json records the kernel identifier, digests, and provenance.
test.json contains correctness cases, so an implementation can be checked against expected behavior.
bench.json contains benchmark and tuning cases that represent the workloads used to evaluate the kernel.
*.wgsl.jinja files contain the parameterized WGSL implementations used to produce shaders for a particular request and device.
This structure turns a shader into a reusable software artifact. The interface is inspectable without reading WGSL, correctness and performance cases travel with the implementation, and published versions can be loaded explicitly rather than depending on an unversioned file URL. Our kernels can also serve as reference implementations for developers building custom WebGPU kernels or integrating these operations into their own runtimes.
Install the package from npm:
npm install @huggingface/kernels@preview
Running these kernels requires a browser with WebGPU support. WebGPU availability depends on the browser, operating system, GPU, and driver. You can check for it in JavaScript with "gpu" in navigator .
@huggingface/kernels provides the bridge between a kernel repository and your application. Call getKernel with a Hub repository ID and a contract version, then invoke the returned function with typed input data and tensor shapes. Here is a small bias-add example:
The second input is broadcast across the first dimension, producing an output with shape [2, 3] . The loader derives that output shape and logical data type from the manifest contract and the inputs, then allocates c automatically.
Addition on six floats is deliberately the smallest possible demo. At this size, the GPU round trip costs far more than the math. The point is the call pattern: it stays exactly the same for the heavyweight operations where optimized kernels actually pay off, such as matrix multiplication ( ai.onnx.MatMul ). Only the repository ID and the inputs change.
Even this elementary operation illustrates why kernels need variants. Equal-shape addition can use a direct vectorized path, while broadcasted inputs need different indexing logic. The published Add kernel includes variants for equal shapes, vectorized broadcasting, scalar processing, and general broadcasting. The runtime can select an implementation that fits the current call and device without changing the application-facing API.
The version: 1 option selects version 1 of the published kernel contract. It is separate from an ONNX opset, an operator's since_version , or a model revision. Keeping those concepts separate lets applications depend on a stable JavaScript-facing contract while kernel implementations evolve behind it.
So, how much of a difference do optimized kernels actually make? We put our collection head-to-head with ORT WebGPU on an Apple M4 GPU, using ONNX Runtime Web 1.30.0-dev.20260826-b1f76d586a . We started with 1,756 test cases across all 207 operations and kept the 809 cases where both sides produced matching outputs and reliable timings.
Across those comparisons, our kernels were 2.57x faster by geometric mean and 1.90x faster at the median, with 629 wins, 176 losses, and 4 ties. Here is a closer look at four familiar operations:
Operation
Compared cases
Our WebGPU Kernel
ORT WebGPU
Speedup
Add
5
0.064 ms
0.227 ms
3.52x
MatMul
29
0.115 ms
0.131 ms
1.14x
Softmax
12
0.114 ms
0.240 ms
2.11x
LayerNormalization
6
0.061 ms
0.135 ms
2.22x
Some individual wins were much bigger. A particularly difficult bilinear Einsum case ( i,ij,j with size 4096) ran in 0.136 ms with our kernel versus 1,396 ms with ORT WebGPU: more than 10,000x faster. A row-wise CumSum over [256, 4096] was 301x faster, at 0.016 ms versus 4.784 ms. These are unusual cases rather than the speedups you should expect everywhere, but they show how much a specialized kernel can help when a general implementation hits a slow path.
We timed the work done on the GPU itself, leaving out setup such as loading kernels, creating sessions, uploading inputs, compiling shaders, and reading outputs back. Very short workloads are naturally harder to measure, and small cases can benefit from the GPU cache, so these numbers are best read as a useful comparison rather than a promise for every application.
They are also results for individual operations, not complete models. Exact performance will change across GPUs and browsers, which is why Fleet is so important for building a broader picture.
We are also working with the ONNX Runtime team to upstream these improvements so they can benefit the broader ONNX Runtime Web ecosystem.
WebGPU performance varies across GPUs, browsers, and drivers, so results from one machine only tell part of the story. Fleet lets anyone run correctness and performance checks in the browser and see how the kernels behave on their hardware.
With consent, each run privately contributes evidence that helps us spot device-specific failures, compare variants, and improve selection rules. The goal is simple: use broad, real-world coverage to make the kernels faster and more reliable for everyone.
The initial 207 kernels are a starting point, not the end state. Publishing kernels independently on the Hub gives us a common place to inspect contracts, compare implementations, reproduce correctness checks, and improve performance without embedding every shader directly into every runtime.
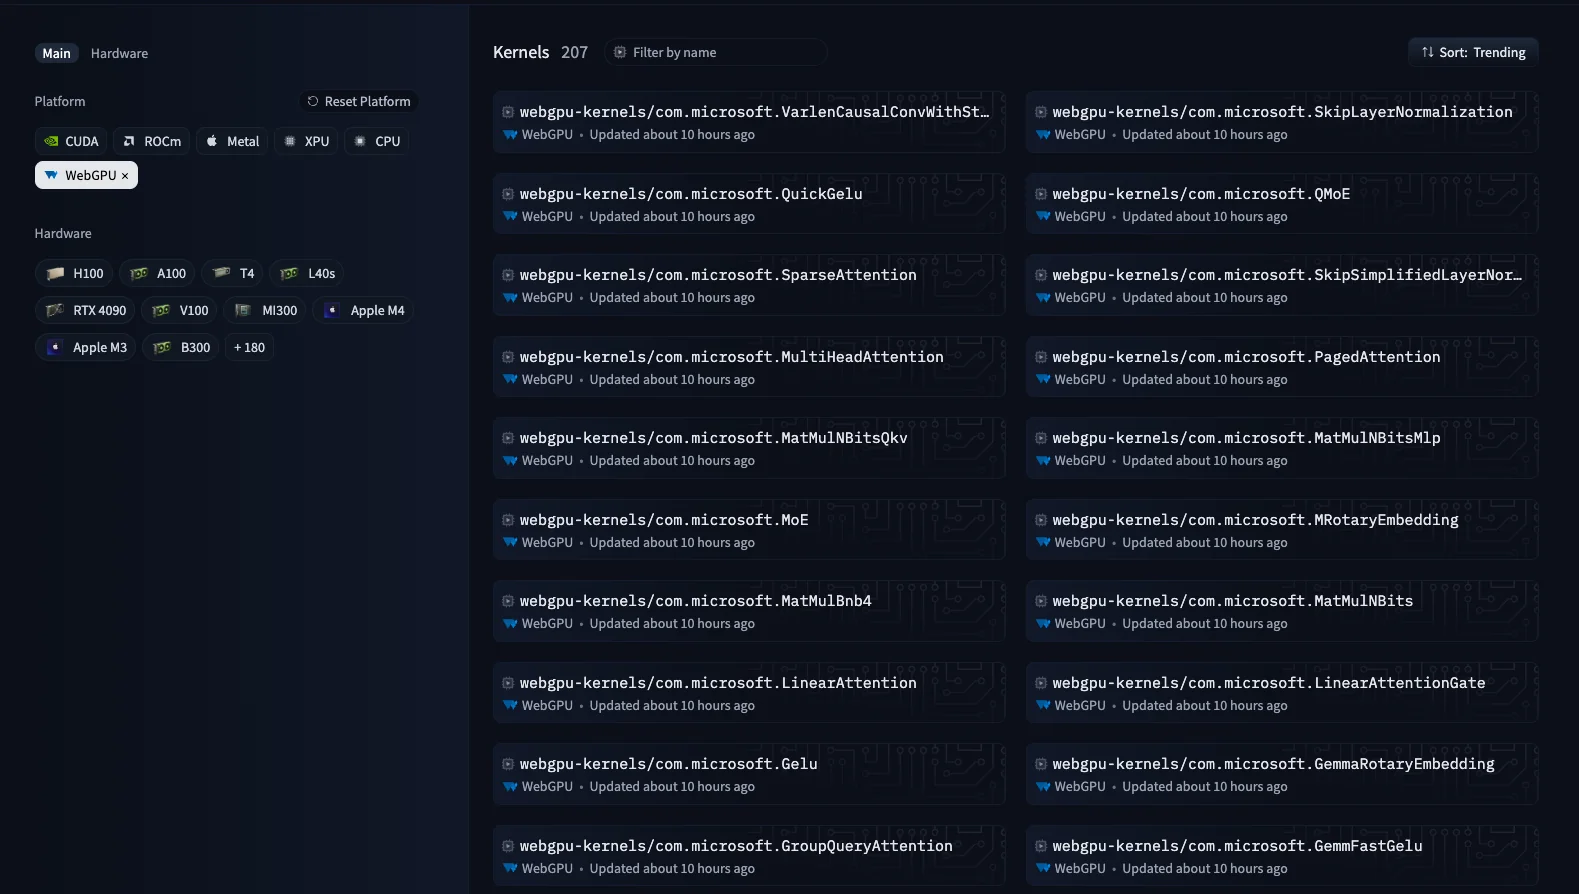
The collection is also part of the Hub's broader kernel ecosystem: on the Kernels page, the WebGPU kernels sit alongside kernels for CUDA, ROCm, Metal, and other platforms, and can be filtered, sorted, and explored like any other artifact on the Hub.
All 207 WebGPU kernels on the Hub's Kernels page , filtered by platform.
@huggingface/kernels makes those operations straightforward to load and run from JavaScript.
Fleet crowdsources real-world evidence across a much broader range of devices than a conventional benchmark lab can cover.
Every contributed run can reveal failures, guide tuning, improve variant selection, and help validate future kernel versions.
This is the low-level foundation for the next steps in our browser inference stack. We are excited to connect these kernels to higher-level model tooling, continue expanding operation coverage, and make fast local inference easier to use across the WebAI ecosystem.
Explore the WebGPU kernel collection, try @huggingface/kernels , and join the Fleet to contribute evidence from your device and help us make the kernels better for everyone.
The source text above remains the property of its publisher and is reproduced for commentary.