Echoverse: Deep Synthetic Worlds Shift Computer-Use Training from Scale to Fidelity and Co-Evolution
Microsoft's Echoverse introduces a pipeline for building deep, stateful synthetic worlds for computer-use agents, and reports that training a 9B model on twelve such worlds raises a baseline from 36.5% to 67.1%, within fourteen points of GPT-5.4. The work argues that fidelity, capability-targeted controls, and co-evolving worlds, tasks, and verifiers matter more than environment count.
Microsoft's Echoverse work reports that training a 9B computer-use model on twelve high-fidelity synthetic worlds improves its baseline from 36.5% to 67.1%, within fourteen points of GPT-5.4. The stated claim is not that more environments add capability, but that depth, capability-targeted controls, and co-evolving the world with the model do. The primary constraint shift is from benchmark scale to a closed loop in which failures update the world, its tasks, and its verifier as well as the model.1
Context
Public benchmarks for computer-use agents drift because open, login-free sites are redesigned, rate-limited, and non-resettable, while consequential work lives behind logins in closed, proprietary systems. Echoverse responds by synthesizing applications whose database state is real, resettable, and graded directly, so actions have true consequences without production risk. The work positions fidelity and coherent state, not pixel appearance, as the training signal.1
Assessment
The evidence is a single vendor blog with high-level experiment summaries, no full evaluation protocol, and no external validation. The reported results are internally consistent, but the causal claim that shallow worlds actively regress the agent rests on unreported numbers. What is genuinely new is the explicit pairing of capability worlds that isolate one UI control with a grounded verifier that measures state changes rather than screenshots.1
Caveats
Releasing only four of twelve worlds limits reproducibility; the remaining eight, including banking, health, and ML consoles, are not publicly testable. The comparison to GPT-5.4 is incomplete without benchmark and variance details. A stronger test would be independent evaluation across multiple held-out live domains and ablations that separate world depth, task difficulty, and verifier quality.1
Scaling fidelity over sheer count, targeting the capabilities agents actually lack, and evolving with the models they train.
At a glance
We built twelve training worlds for computer-use agents: ten deep domain worlds and two capability worlds, each drilling a single control rendered in many forms (date pickers and nested filters). Depth is what makes them worth training on: these worlds reproduce an application’s real behavior, come seeded with realistic data, and keep state coherent across screens and users. Trained on all twelve, a 9B model nearly doubles its base score (36.5% to 67.1%), coming within fourteen points of GPT-5.4. The experiment taught us several lessons:
High simulation fidelity is a must-have; shallow worlds hurt the agent. Trained on shallow and deep builds of the same sites, the model regressed on the shallow ones but improved on the deep ones.
Agents often struggle with the same challenging UI elements, like date pickers and nested filters. Drilling those controls in varied forms taught the model to operate them in domains it never saw in training.
Co-evolving the model, the world, and the verifier improves all of them. As the world grows more correct and its tasks grow harder, the model climbs with it.
Reinforcement learning against the worlds pushes the agent past imitation. Using the grounded verifier as the reward, RL lifts held-out performance and teaches the agent to reach the goal in fewer steps.
We’re releasing four of the worlds with their code, data, and grounded graders, to support research on high-fidelity computer-use worlds. Github: microsoft/Echoverse: Deep, Evolving Environments for Computer-Use Agents (opens in new tab) Hugging Face: microsoft/Echoverse · Datasets at Hugging Face (opens in new tab) Technical Report: https://www.microsoft.com/en-us/research/publication/echoverse-deep-evolving-environments-for-training-computer-use-agents-at-scale/
A computer-use agent learns the results of what its actions do only where they have real consequences. A click changes saved state, a message reaches a real person, or a page that refuses to move tells the agent its last move did nothing. A screenshot can show what an interface looks like, but only a working world shows what an action caused.
The consequences worth learning from are stateful, and most of them sit behind a login. The work people want automated lives in closed systems: email and chat, banking, health records, the internal consoles for cloud and ML. You cannot train an agent against the live versions of these. Every attempt writes to a real account, there is no reset between tries, and the true state stays hidden behind the screen. So you rebuild the system as a synthetic world where the database is yours: the state is real and changes for real, but it is safe to break, quick to reset, and graded from the data rather than a screenshot.
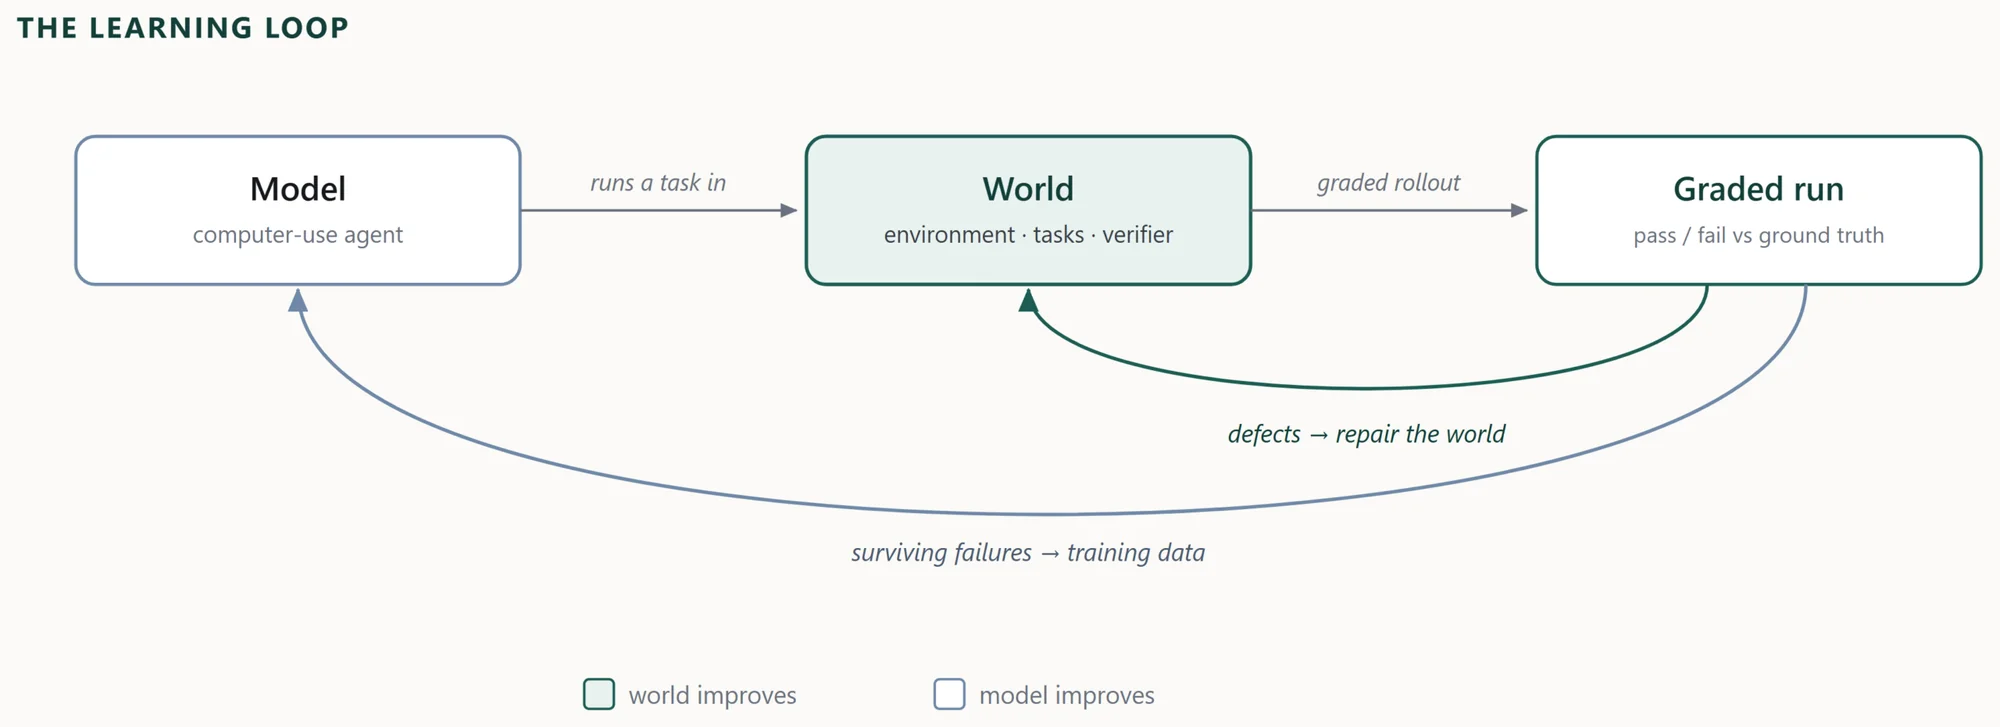
By a world we mean three things bound together: an environment (the application, its state, and the actions that change it), the tasks that set goals in it, and a verifier that grades the outcome against ground truth. The community is now good at making them: pipelines stand up an application, seed it, generate tasks, and attach verifiers, yielding hundreds of environments and thousands of checkable tasks. This work builds on that progress. However, once worlds are plentiful and its internal structure becomes the bottleneck: regardless of whether state stays coherent across users and screens, workflows keep their dependencies, a weak skill recurs in enough forms to generalize, and success is judged by outcome or by appearance.
Our bet, the one Echoverse tests, is that the real leverage comes less from adding worlds than from a loop that keeps improving the ones you already have. It treats building the environment and training the model as one process, not two stages: run a model in a world, find where it fails, make the world, its tasks, and its verifiers more faithful or more demanding there, train on the sharper signal, and repeat. Ordinary fine-tuning improves only the model. Here the same graded run that measures the model also improves the world that judged it, so a static benchmark saturates while the loop compounds.
Three levers keep that loop productive, none of them raw environment count. Depth: behaviorally faithful worlds for the domains that matter, including the closed and proprietary ones. Capability targeting: narrow worlds built around the exact interaction a model keeps failing. Co-evolution: improving the environment, its tasks, and its verifiers on every graded run, not just the model.
Figure 1: The learning loop: every graded run is read twice. Surviving failures become model training data, and defects in the world, its tasks, or its verifier become repairs. The same graded run that measures the model also sharpens the world.
Why synthetic, and why deep?
Open, login-free sites might seem to remove the need for synthetic worlds, but they make a poor training ground for a different reason: they will not hold still. Pages get redesigned, listings and dates roll forward, and hosts throttle or block automated traffic, so a benchmark that is pinned to them drifts, and no two runs face the same site. An occasional evaluation can absorb that; training cannot, since it runs the same task thousands of times and needs the same world each time. A synthetic world is fixed in time and data: the calendar does not move, the seed data does not churn, and a task means the same thing on the thousandth rollout as on the first. We trade a little surface realism for a world we fully control.
Control is only the floor. A world can be perfectly stable and still be hollow, so what earns training time is depth: not its page count but how faithfully it preserves the causal structure of the work. Five properties set the bar: behavioral fidelity (controls, permissions, and errors follow the product’s logic); coherent state (a sent message appears for its recipient, a cancelled meeting clears both calendars); workflow depth (an early choice constrains what happens later); authoritative verification (application state, not pixels); and domain value (the workflow is worth improving). In the systems that matter most, the difficulty lives in permissions, shared state, and audit histories: exactly the structure a shallow clone skips. Above this bar, more environments add variety; below it, they add noise.
How the Echoverse factory works?
Echoverse is a single pipeline with two outputs: full domain worlds that preserve workflow depth, and capability worlds that vary one diagnosed interaction. Both lean on the fact that we own the database underneath, so success is a property of the app’s own state, not a model’s read of a screenshot.
Building the world
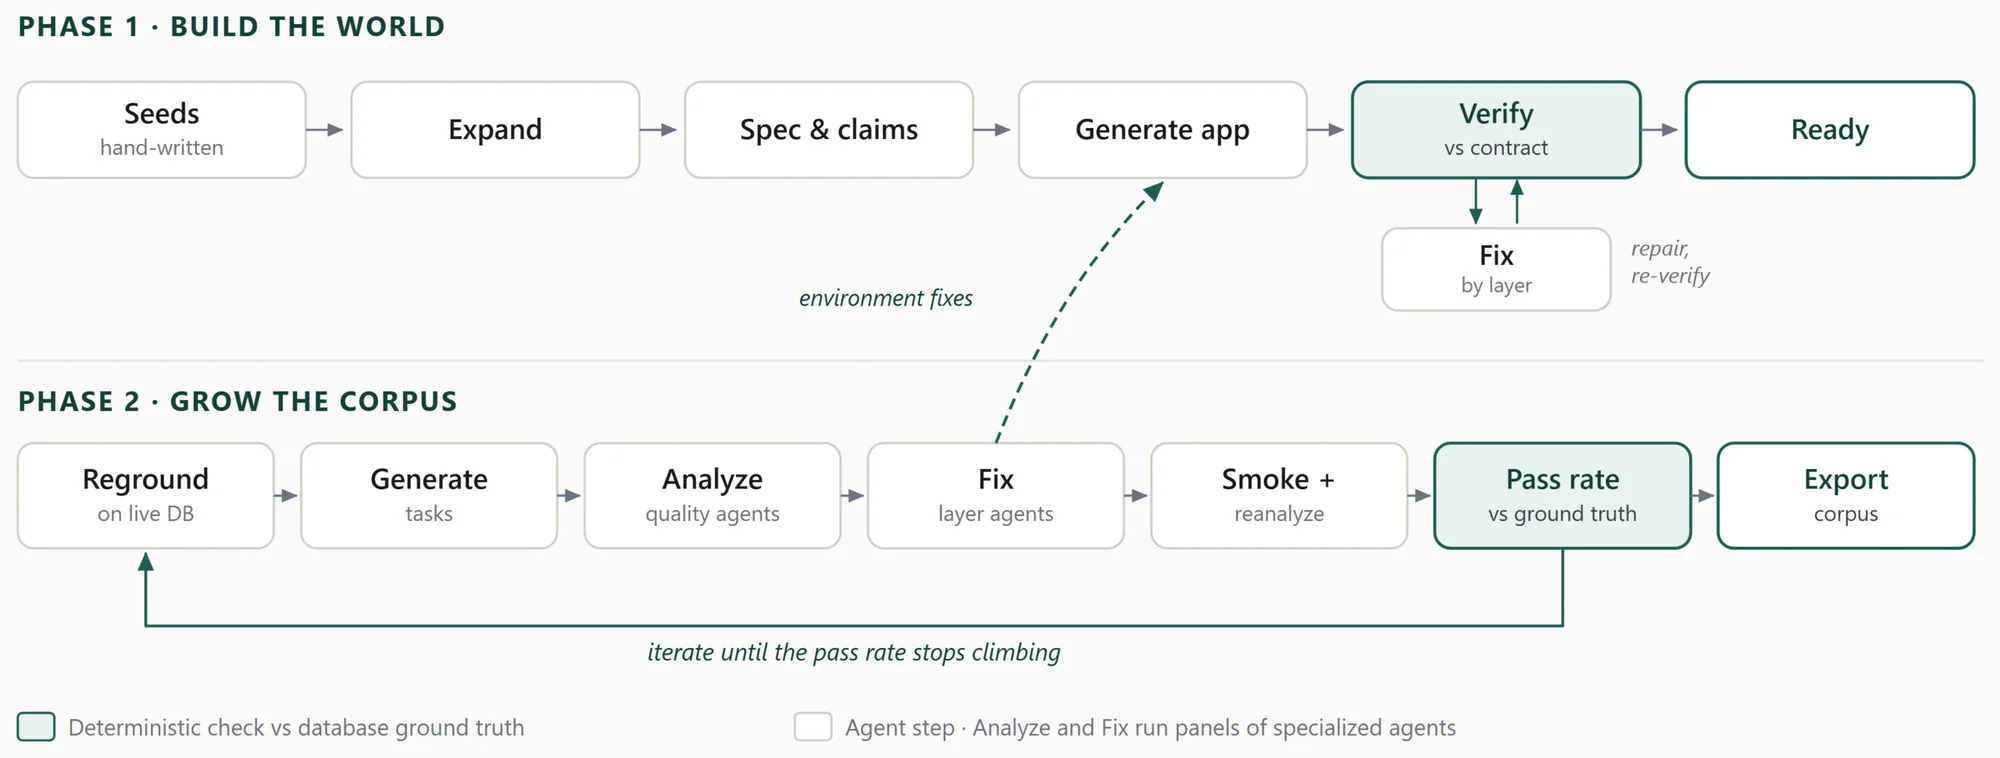
The pipeline expands a handful of seed scenarios into a spec, then compiles it into machine-checkable claims about routes, state, and behavior. Only then does it generate the app: a FastAPI and SQLite backend under a React interface. A fresh app is a hypothesis, not a world: the builder runs every claim against the running environment, repairing the database, backend, or frontend until each passes, then writes a readiness record that separates hard blockers from advisory risks. A world with open blockers does not advance. Depth here is not a promise in a prompt; it is the list of claims the world has been shown to pass.
Growing the corpus
A world that builds cleanly is still not training data. We reground each task on the live database, drawing goals from entities that actually exist, then send every goal through a panel of analyzers: are its entities real, is the goal plausible, does its difficulty match the work, and, the sharpest test, can an agent driving the real UI complete it? That last check runs in the browser, catching goals no interface can satisfy before a model ever sees them. A generated goal is a claim; a solve against the real app is proof.
Every failure becomes an issue tagged by the layer that must change: database, backend, frontend, task text, or verifier. Layer-specific fixers apply the repair, re-check it against the running app, and roll it back if it regresses. The loop re-scores against database ground truth until the pass rate stops climbing, and each surviving task is exported carrying the exact check that grades it. Those tasks become training data through one process: GPT-5.4 solves each task, a verifier keeps the trajectories that pass ground truth, and those become the supervised fine-tuning (SFT) data behind every experiment below.
Building the world and growing the corpus are not two stages but rather one loop: most defects belong to the world, so we re-version the environment with every iteration. Harder tasks expose gaps in the world, and a sturdier world can carry harder tasks, so each round leaves both stronger.
Figure 2: The environment factory: the two loops behind every world. Phase 1 expands a handful of seeds into an app, then repairs the database, backend, and frontend until it passes machine-checkable claims. Phase 2 regrounds tasks on live data, runs a panel of analyzer and layer-specific fixer agents, and re-scores against database ground truth until the pass rate plateaus. Many of those fixes land in the world itself (dashed arrow).
The verifier is grounded in the database
Every task carries its own answer key, a value or a state change minted from the real database by a SQL query at generation, true by construction and re-checked after the agent finishes. A read is graded on semantic equivalence to the stored value ($288 for $287.62 passes); a write on a real before/after database diff, so claiming a ticket was closed fails unless the row flipped; a read_write scores the lower of the two. Grading is hard to game, grounded rather than labelled, and uniform across an EchoStay booking, an EchoForge issue, and an EchoBank transfer.
Full domains carry the workflow
The domains with the most consequential work are the hardest for public benchmarks to reach: closed, proprietary systems where the difficulty lives in permissions, shared state, and history, not layout. A faithful clone has to reproduce that. What matters is not the pixels but that an action’s consequences reach across screens and users, so a task can run a real workflow and be graded on the state it leaves behind.
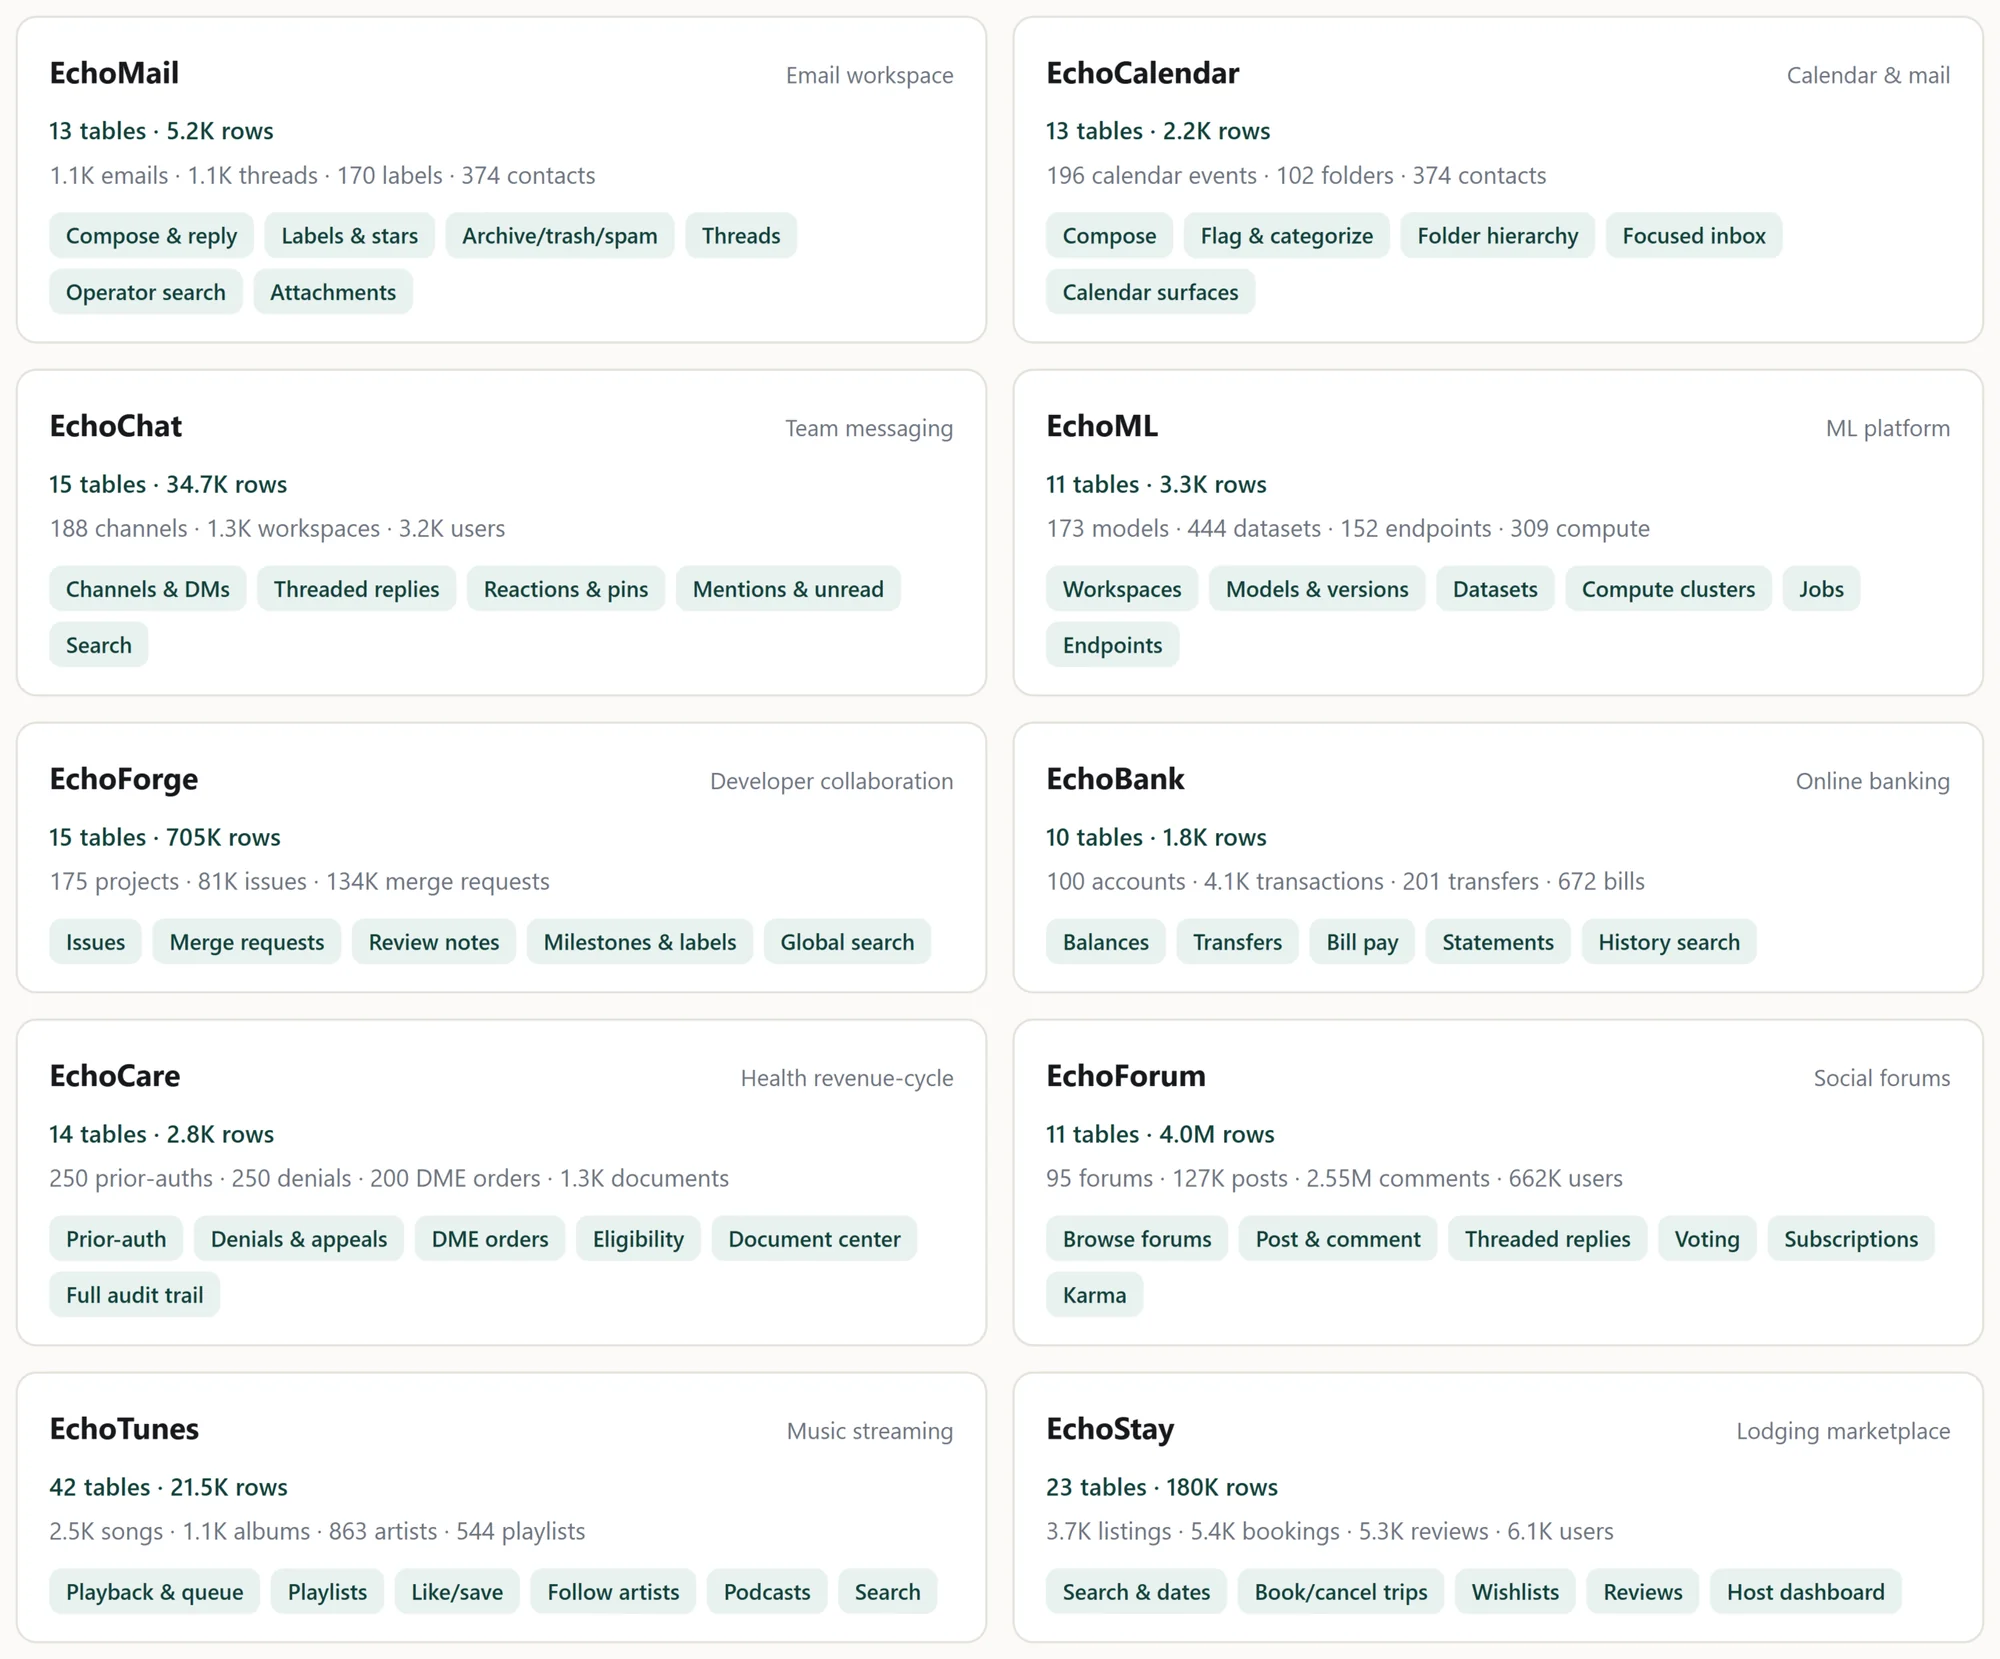
The ten Echo domains span communication, technical work, regulated records, community, media, and travel. Where a rich public dataset exists we build on it: EchoStay is seeded from InsideAirbnb, so its listings, hosts, reviews, and amenities are real rather than invented, and EchoForum sits on a public forum corpus of 2.55 million comments. Where none exists, as with mail, calendar, banking, and health records, a seeding pipeline generates the state under strict constraints, dense and internally consistent, not a handful of placeholder rows.
Balances or records, authorization, audit history, consequential writes
Community, media & travel
EchoForum, EchoTunes, EchoStay
Persistent preferences, social state, search, booking, account actions
That accumulated state is what makes an action’s consequences reach across screens and users. A booking in EchoStay moves through search, listing, availability, and payment across roughly 87 routes and 23 tables, but not a single confirmation screen; an EchoMail thread carries intent from draft through delivery, reply, and label state; an EchoCare order writes each change to an audit trail. The tasks are expensive because of it, often five to twenty actions deep, and finished only when the underlying state has changed.
Figure 3: Per-domain detail across the Echo suite. Each ships as a self-contained, fully-interactive clone of the app it models, with its own backend, seeded database, and feature surface. Counts are grounded database state, not mockups.
Capability worlds isolate one skill
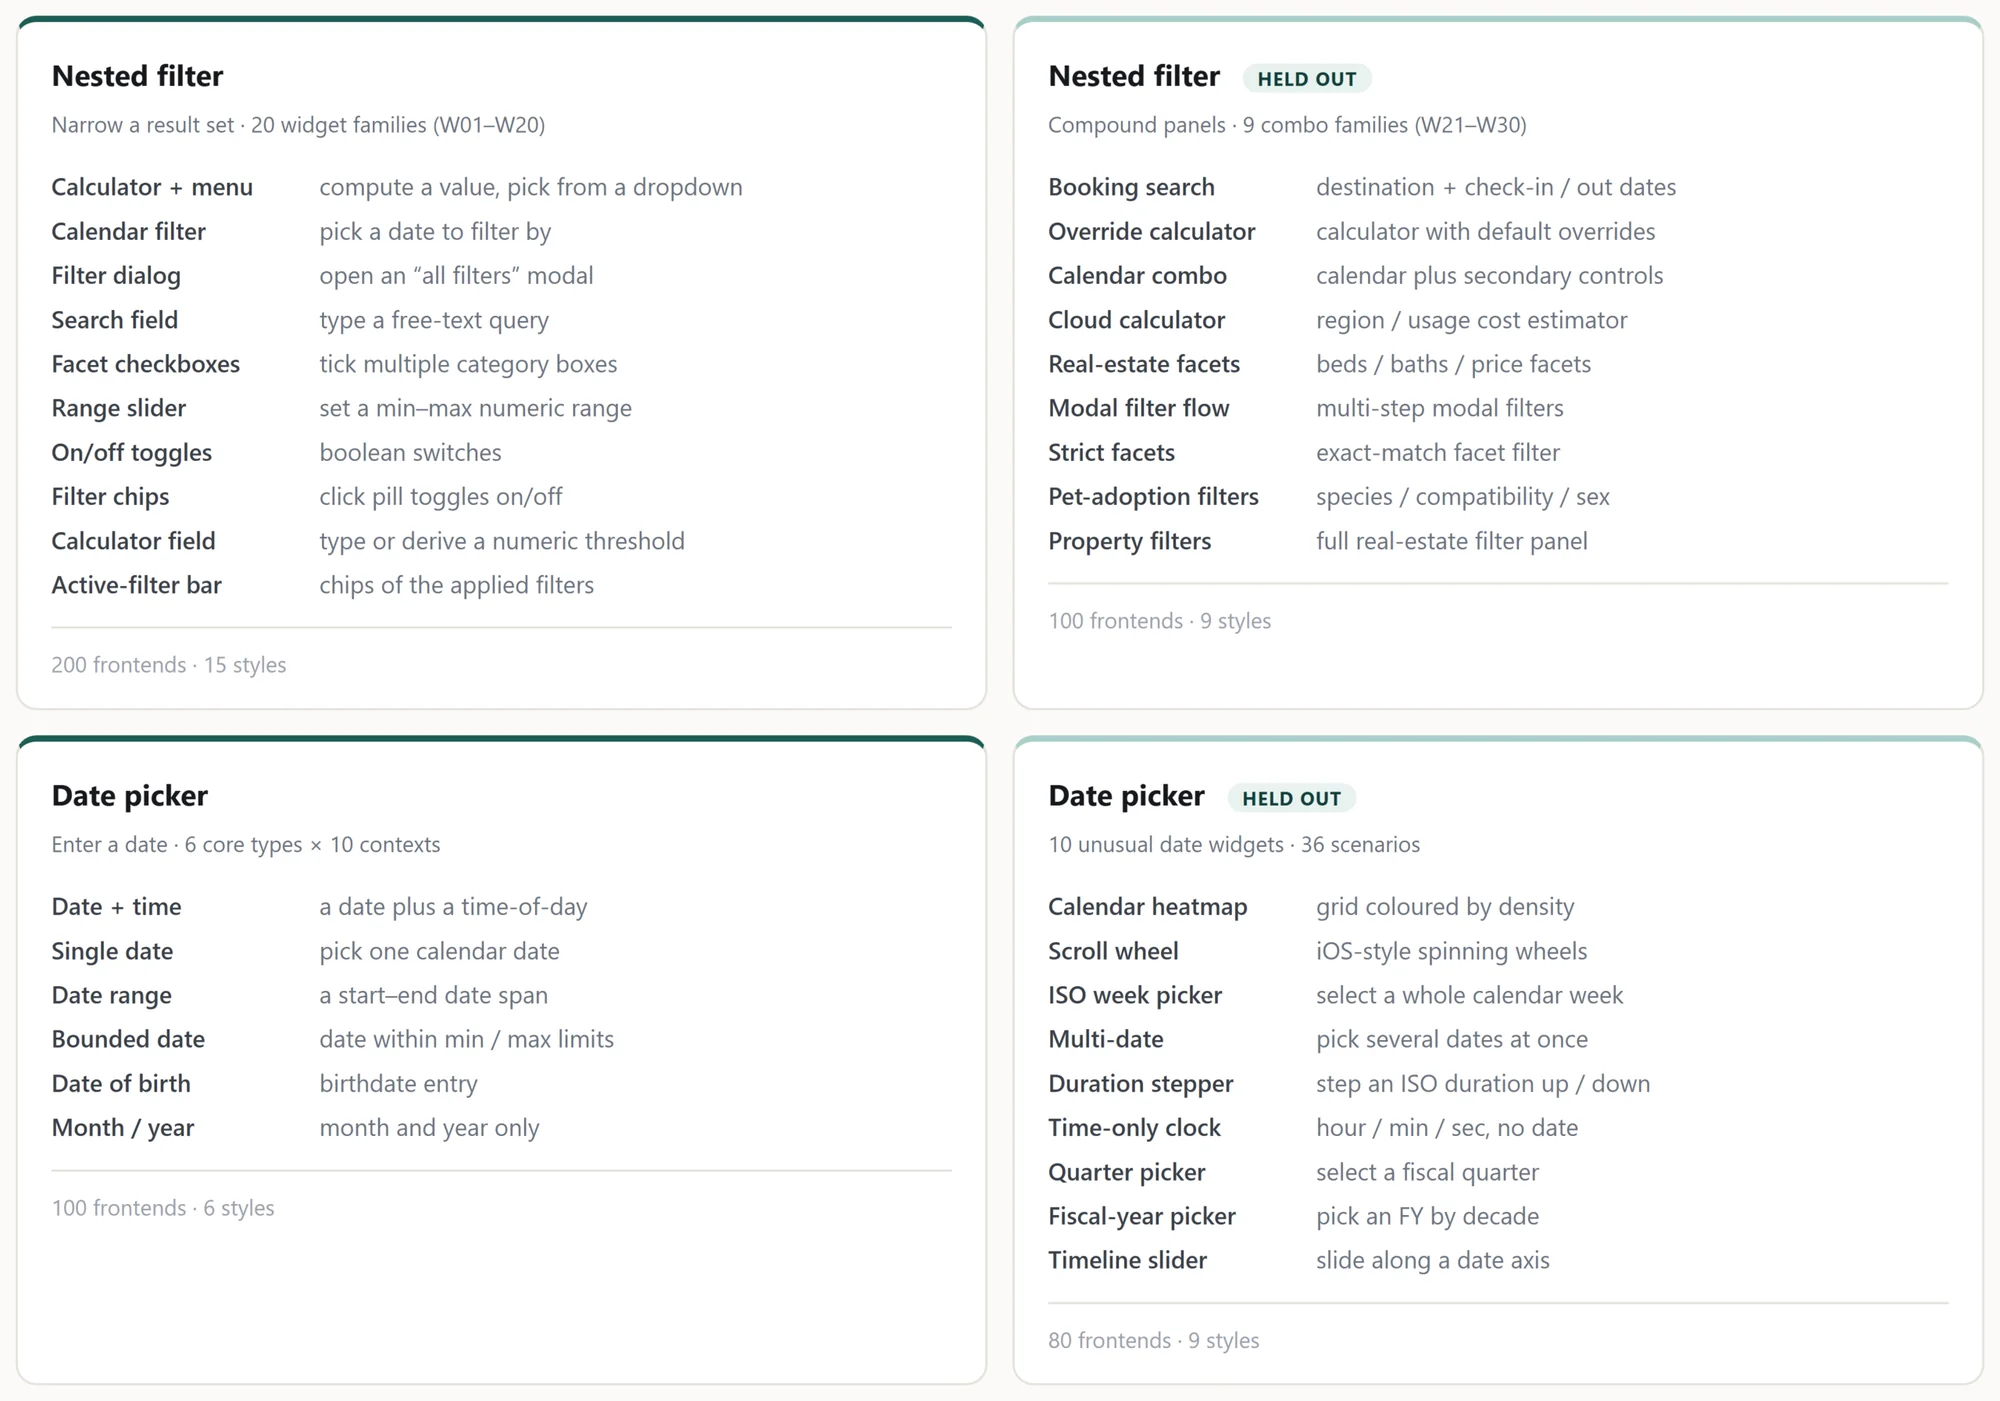
Not every weakness represents a missing domain; some are caused by a single control that the agent cannot reliably operate. Picture an agent booking a trip: it searches, filters, opens the right listing, then stalls at the date picker, unable to turn “the second week of March” into the right clicks on an unfamiliar calendar. Building another booking site would not fix that. The skill is learned only when the control itself appears in enough forms, and date pickers and nested filter-and-search are ubiquitous on the live web, rendered a hundred different ways, exactly the variability a single deep app cannot supply.
So we isolate the control and widen the interaction, mass-producing it across layouts, states, and constraints, then generating grounded tasks over each. The datepicker world renders one date control as six core widgets across 10 contexts and holds out 10 new unseen ones, from calendar heatmaps to scroll wheels and fiscal-quarter pickers; its hardest tasks turn transcription into reasoning, resolving “the last Thursday of January 2026” or “10 business days after a start date” to one exact, widget-reachable date. The nested-filter world varies 20 widget families and holds out nine compound-panel families as out-of-distribution, grading every submission by whether the filtered results actually meet the requested conditions, judged by the app’s own logic rather than by appearance.
Figure 4: Every widget family the two skills cover, split into training (in-distribution) and evaluation-only (held out): nested filters, 20 families plus 9 held-out compound panels; date pickers, 6 core types across 10 contexts plus 10 held-out widgets.
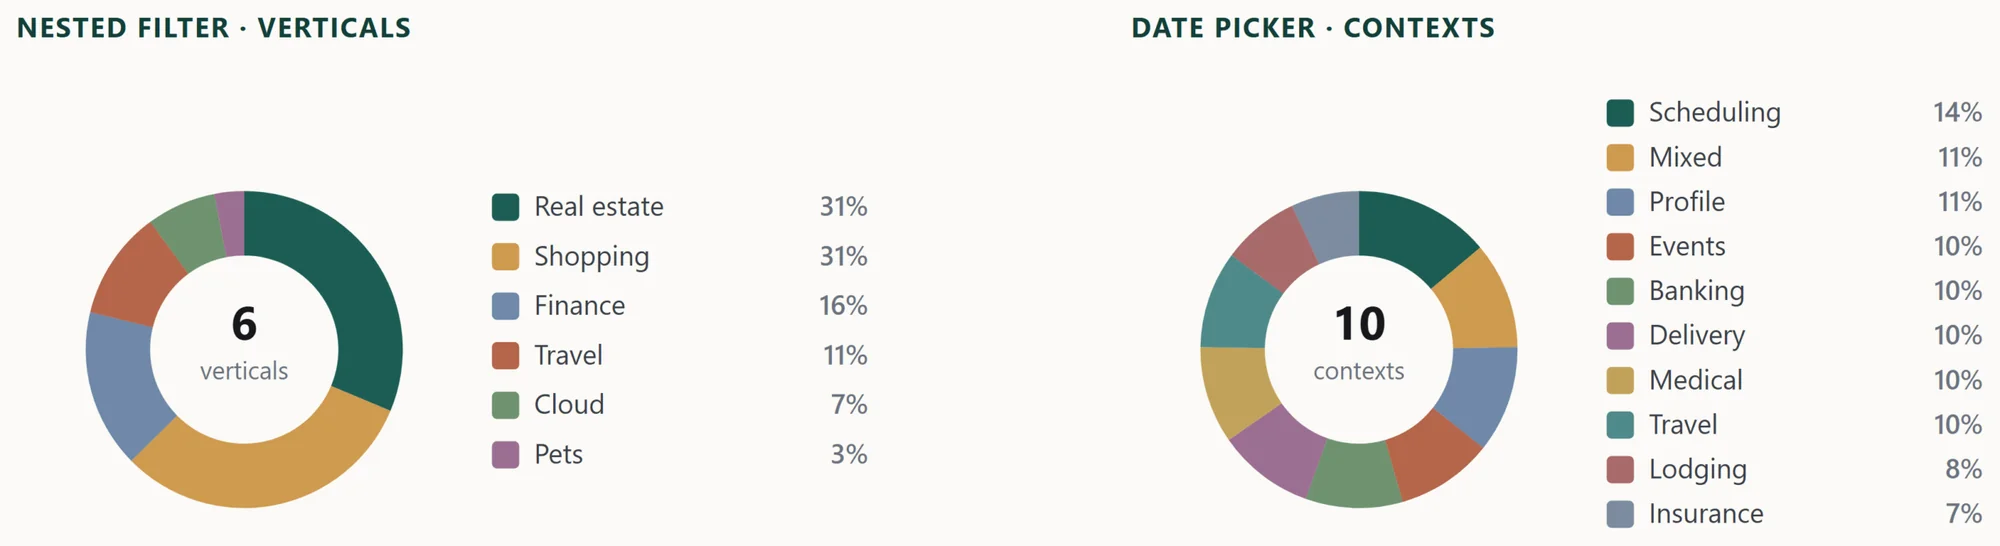
Figure 5: Date pickers and nested filters themed across domains: nested filters over six verticals, from real estate to pet adoption; date pickers over ten contexts, from scheduling to insurance.
What deeper, targeted worlds change
More trajectories do not automatically provide more training signal. What matters is depth: whether an episode carries a task through the dependent steps of a real workflow rather than just rehearsing an action in isolation. Two experiments make the difference concrete from opposite ends: one goes deeper on a whole domain, the other narrows to a single broken skill.
Shallow worlds backfire; deep worlds transfer
A shallow world is the cheap option. It stands up fast and looks convincing, but it only rehearses isolated, correct-looking clicks. Train on that and the model will pick up the wrong reflexes, over-stepping and looping and repeating dead actions, because nothing in the easy world ever punished them. A deep world costs more, but its trajectories carry the dependent structure that transfers to the live site.
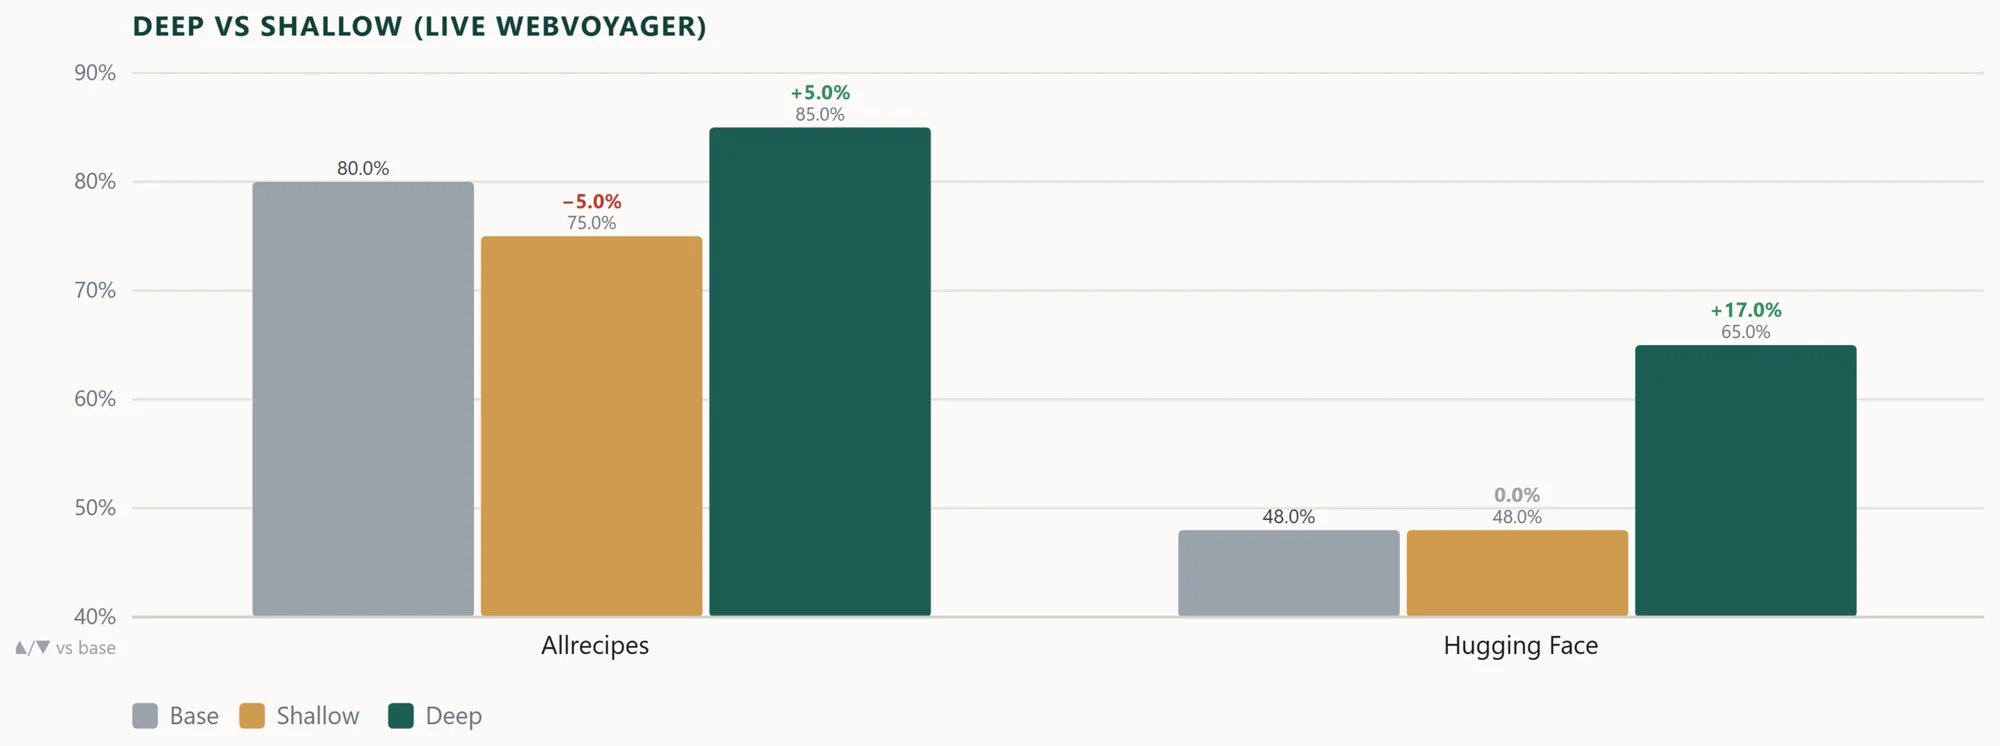
To isolate that, take two live WebVoyager domains, Allrecipes and Hugging Face, and compare three checkpoints: the base model and two trained on shallow-world and deep-world trajectories built for those domains. The shallow world poses short, self-contained tasks; the deep world poses tasks that run across dependent steps, where an early action changes the state, options, and verification available later. Both give the model the same domain exposure, so only depth differs, and evaluation uses tasks from the public WebVoyager benchmark for these domains, run on the live sites outside any training world.
On Allrecipes, the shallow world pulls the model down, 80.0% to 75.0%; on Hugging Face it stays flat at 48.0%. Only the deep world improves both, lifting Allrecipes to 85.0% and the harder Hugging Face split to 65.0%. With exposure held equal, the gap is depth: the deep model loops less, and of the 37 Hugging Face tasks, those that exhaust their step budget fall from 15 to nine. What separated the two was not how much the model saw, but whether what it saw preserved the structure of the work.
Figure 6: Deep versus shallow worlds for two live WebVoyager domains, with identical domain exposure and different task depth. Deep lifts both; shallow drops below base on Allrecipes and stalls on Hugging Face.
Precision about one skill
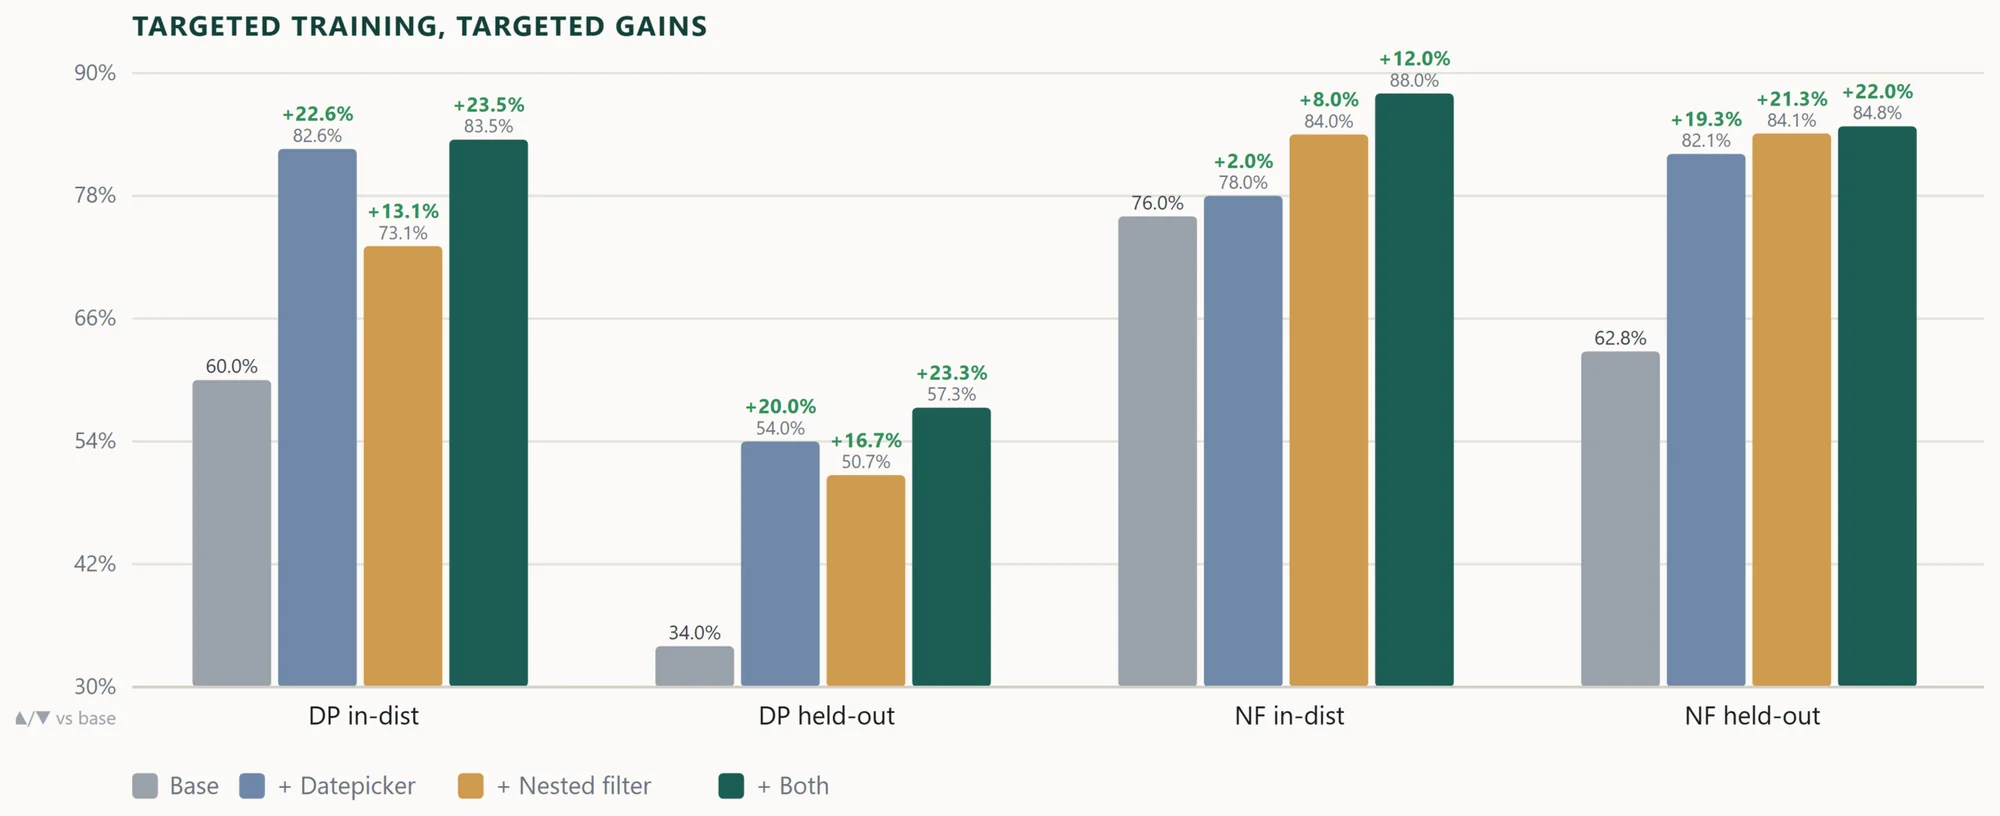
The datepicker and nested-filter worlds drill exactly the controls our evaluations flagged, and the two skills reinforce each other. Datepicker training lifts datepicker evaluations (in-distribution 60.0% to 82.6%, held-out layouts 34.0% to 54.0%); filter training lifts held-out filters 62.8% to 84.1%. Gains that hold on forms never trained on indicate that the model learned a rule, not a layout. The skills transfer across each other rather than competing: training either one alone still lifts the other, and training both is the best all-rounder on every split. Against GPT-5.4 as a frontier reference, that combined model already edges ahead on nested filters and closes most of the datepicker in-distribution gap, trailing clearly only on held-out datepickers. And the rule reaches the open web, lifting Online-Mind2Web 29.5% to 34.3% on sites it never saw.
Figure 7: Targeted training, targeted gains: training either date pickers or nested filters lifts both controls, including held-out widgets and compositions neither was trained on, and training both is the best all-rounder on every split. Higher is better.
From synthetic worlds to the live web
Three models run through the rest of this section. Base is Qwen3.5-9B given only a handful of synthetic trajectories, just enough to align a general model to the browser action space. Our model is that same 9-billion-parameter network trained on the full synthetic corpus. GPT-5.4 is a far larger frontier model, included as a reference ceiling.
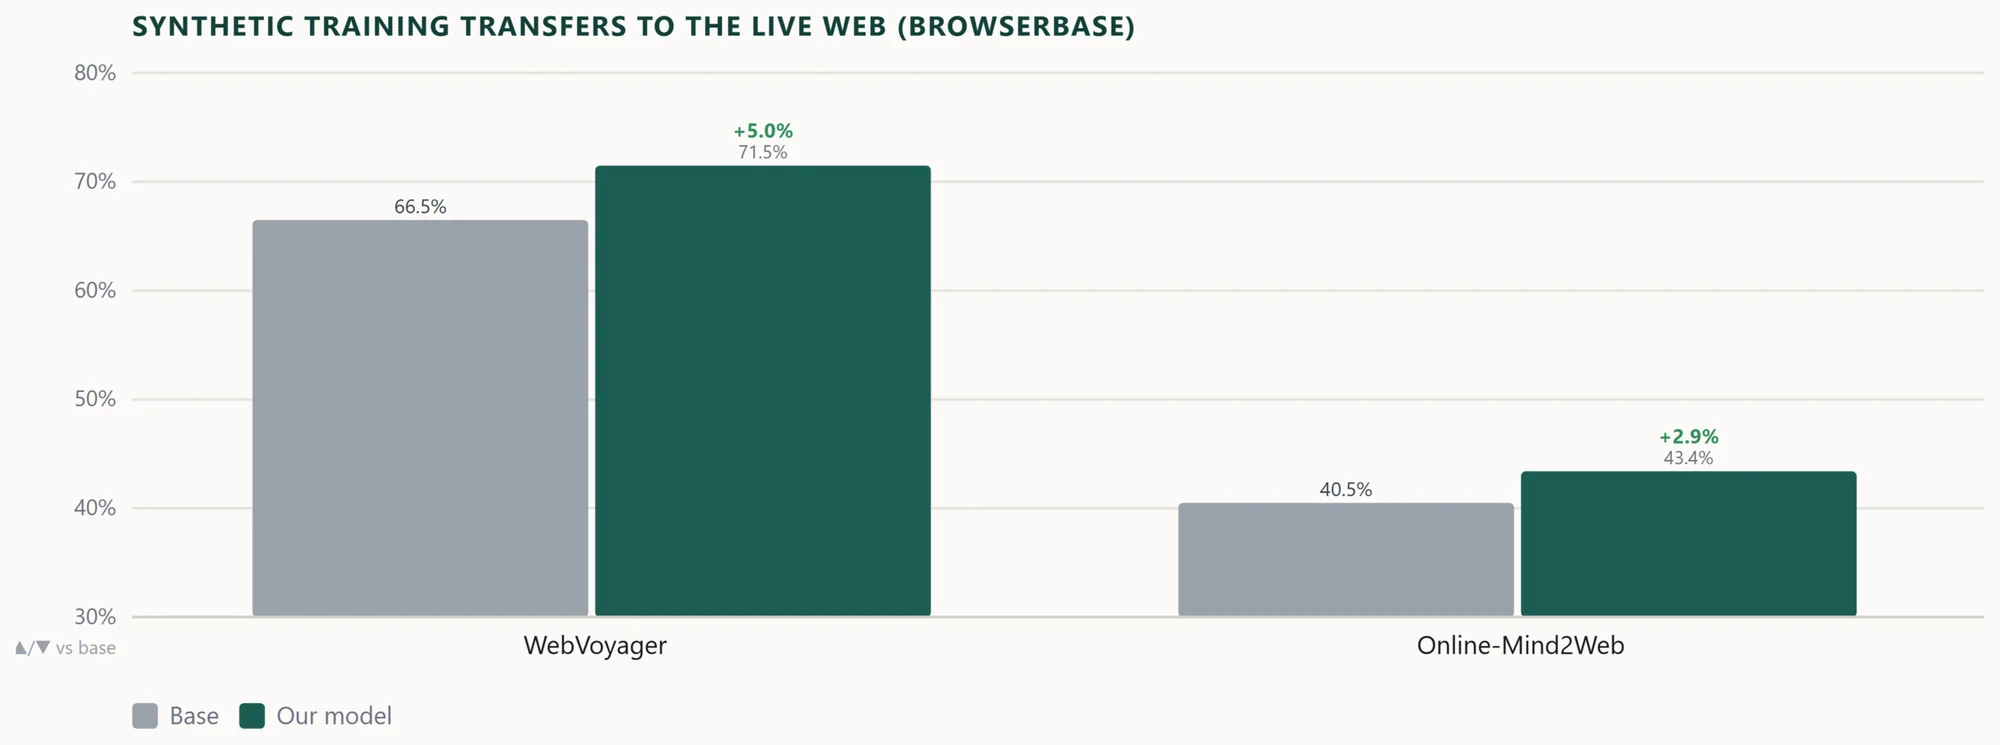
Does the skill survive the open web? We evaluate our model, unchanged, on WebVoyager and Online-Mind2Web, benchmarks it never trained on. They barely overlap with what we built: both are dominated by open, public sites and read-mostly browsing, while our worlds train login-gated, write-heavy workflows. A large jump was never the point; direction is. The frozen model clears base on both, WebVoyager 66.5% to 71.5% and Online-Mind2Web 40.5% to 43.4% (without BrowserBase, 50.9% to 55.6% and 29.5% to 37.2%), reported through BrowserBase because a hosted browser strips the datacenter bot-blocks and rate limits that otherwise depress every agent’s score. With no live-web data in the mix, this is transfer, not memorization.
Figure 8: Synthetic training transfers to the live web. The full-corpus model, on two benchmarks it never trained on, clears base on both; scores run through BrowserBase to remove datacenter bot-blocks.
The modest live-web gain is a coverage effect, not a ceiling: aim at a live domain and it grows. EchoForge, our code-hosting world, is the same kind of app as GitHub, one of the live sites WebVoyager tests. Add EchoForge to the training mix and the live GitHub score climbs 58.5% to 63.4%, with the overall live scores rising too (WebVoyager 50.9% to 52.9%, Online-Mind2Web 29.5% to 31.1%). The average simply reflects that most of what we built sits in domains these benchmarks never touch.
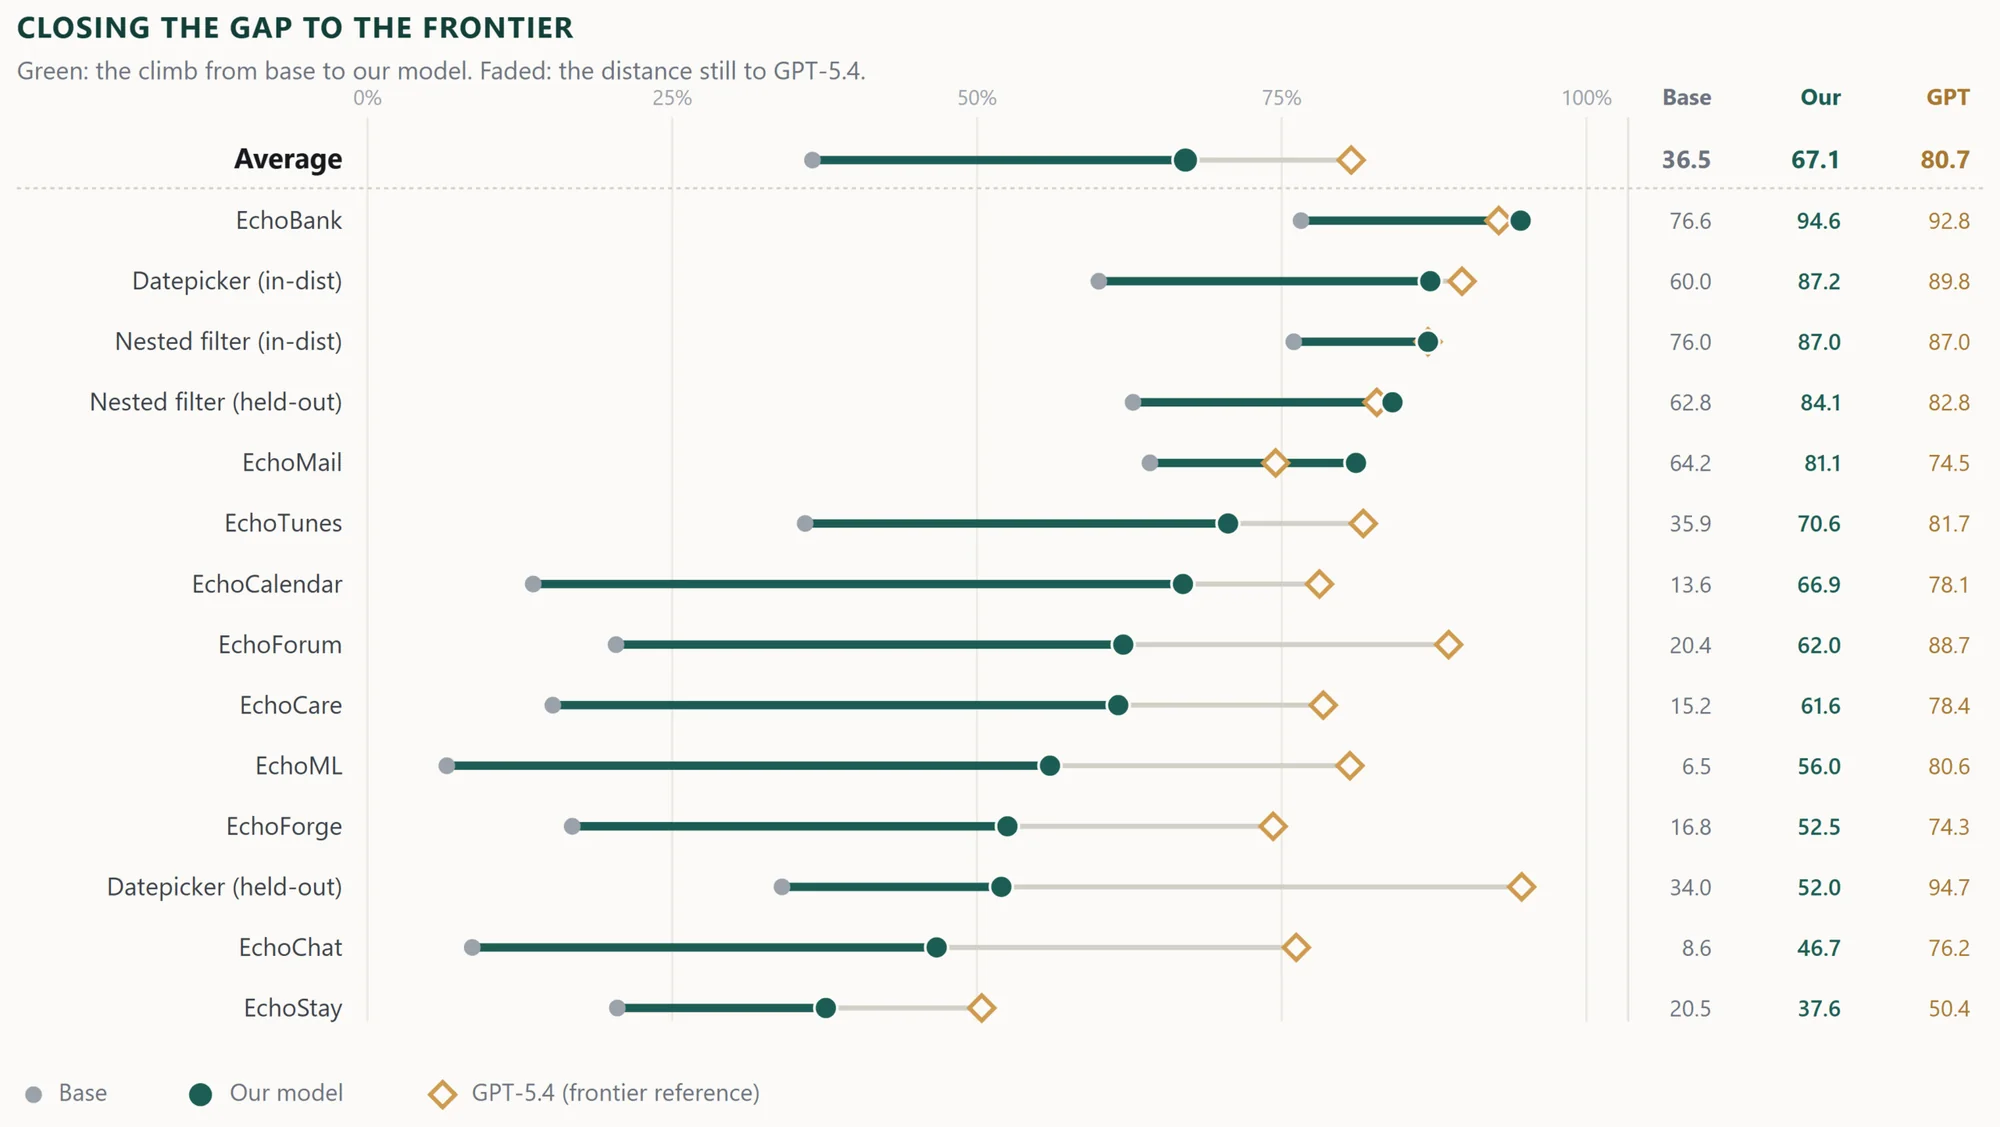
Figure 9: Closing the gap to the frontier, per environment. The green bar is the gain from base to our model; the faded remainder is the distance still to GPT-5.4. Our model surpasses GPT-5.4 on EchoBank and both nested filters and closes most of the gap elsewhere; each model’s exact score is labelled on the right.
The domains we built, most of them closed and login-gated, tell the opposite story. Across all fourteen, the model nearly doubles base, 36.5% to 67.1%, and where base was weakest it climbs three- to nine-fold, with EchoCalendar, EchoML, EchoChat, EchoCare, EchoForge, and EchoForum all moving from single or low double digits into the forties through sixties. That puts a 9-billion-parameter model within fourteen points of GPT-5.4 on the average (67.1% against 80.7%). On EchoMail, EchoBank, and both nested filters, it matches or beats the far larger frontier model outright, trailing by only a few points on in-distribution datepickers. What gets a 9B model this close is not scale but training data that is deep, targeted, and checkable, exactly what the factory is built to produce.
What scaling buys, and what it doesn’t
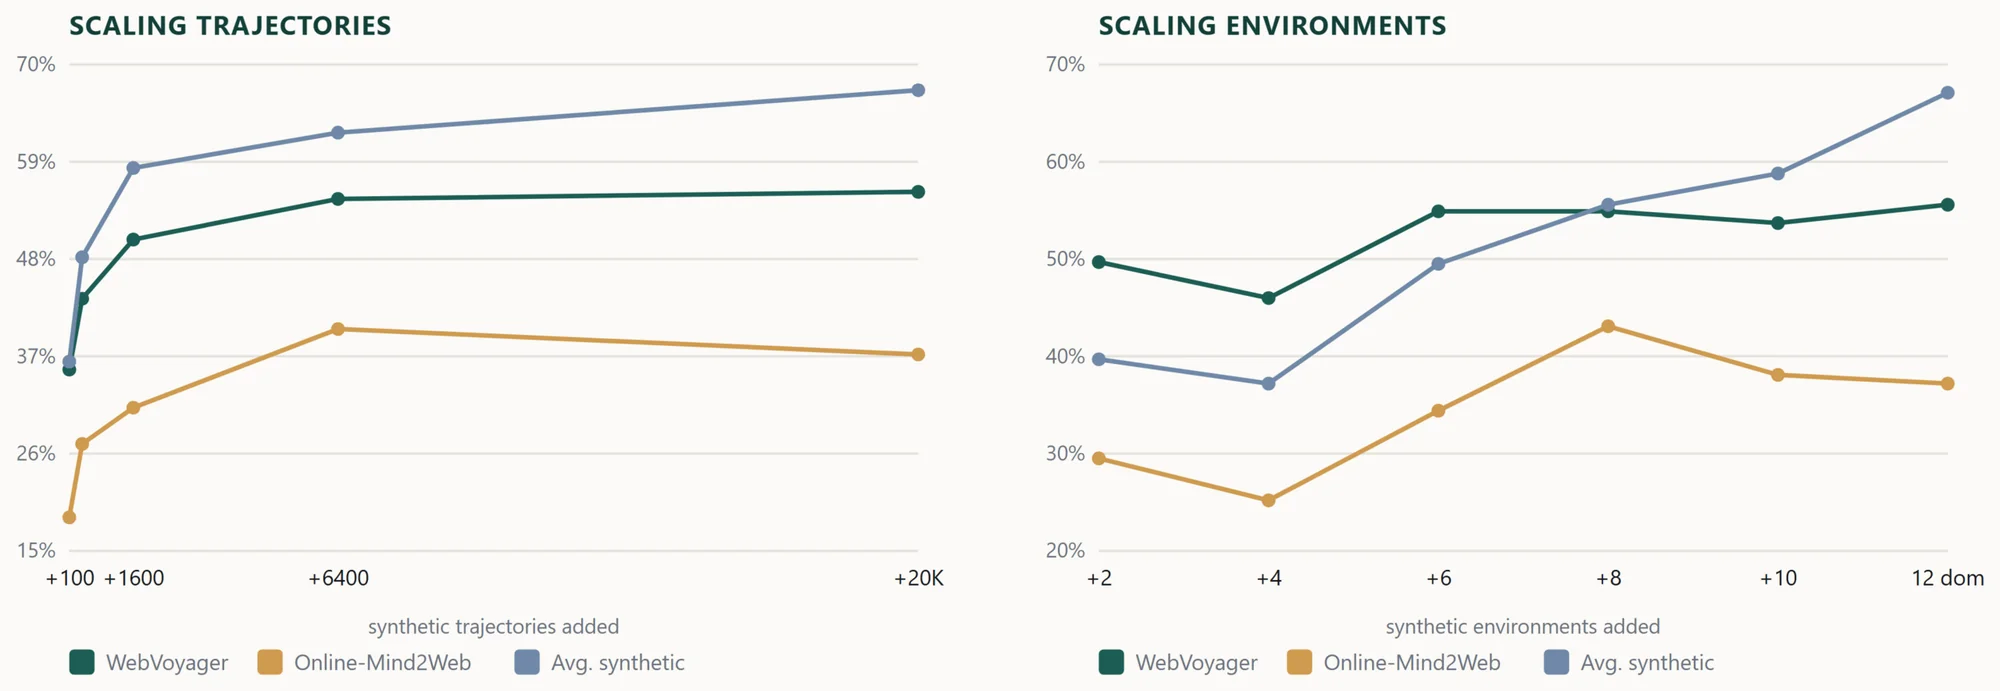
We scaled two axes separately: more trajectories through a fixed set of environments, drawn in equal numbers from each, and more distinct environments. They behave differently. More trajectories on the same worlds keep lifting the in-domain average, though the gains keep shrinking, while transfer to the live web flattens outright: from 6,400 to 20,000 trajectories, WebVoyager holds steady (54.8% to 55.6%) and Online-Mind2Web slips (40.1% to 37.2%). Since every point samples the worlds equally, this is no artifact: each environment holds only so much transferable skill, and once a model has drawn it out, more rollouts mostly polish what it already does.
Scaling environments produces the opposite result. The average keeps climbing as breadth grows, and WebVoyager reaches its best only with the full set. For generalization, the lever is diversity, not volume. A model reaches sites it never saw by training across many kinds of work, not by seeing one kind many more times.
Even so, scale itself is not the lever on either axis. A large trajectory budget spent on shallow worlds, or graded against the wrong answer, moves the synthetic number and goes nowhere on the live web. What travels is inside each trajectory: depth that preserves a real workflow, targeting that drills the control an agent fails, and database-grounded grading that keeps the signal honest.
Figure 10: Two scaling axes, scored without BrowserBase. Left: more trajectories on a fixed set of worlds, drawn in equal numbers from each, with the x-axis spaced by actual trajectory count. The synthetic average keeps rising, but live-web transfer saturates, WebVoyager flat and Online-Mind2Web slipping past 6,400 trajectories. Right: more environments, where breadth keeps the synthetic average and WebVoyager climbing. Diversity of environments, not trajectory volume, is what carries skill to unseen sites.
The model is not the only thing that learns
The score an agent earns is never the model alone. It comes from a coupled stack: the agent, the environment, the task, and the verifier. A zero can mean the agent failed, or the control is broken, or the requested state is impossible, or the verifier checks the wrong thing. Reading every zero as model supervision trains on defects that should have been repaired. So, we read every graded rollout as a test of the whole stack and let the whole stack learn. The environment improves as broken controls and wiring get fixed, the tasks as goals are re-grounded and made harder, the verifier is fixed when it drifts out of sync with the data. Only failures that survive all three become model curriculum.
EchoStay made this visible. Its failures traced to the world, not the agent: a guest-count control silently broke booking tasks, so a correct booking could never register. Fixing it raised the share of those bookings that could be completed at all from 48% to 78%, recovering 15 of the 24 that had been blocked. The same loop finds different faults elsewhere: EchoForum needed frontend fixes and a page-load speedup, which took one failing set of 37 tasks from 0 solved to 36; EchoChat’s verifier had drifted out of sync with the data, and realigning it lifted the share of gradable tasks from 34% to 99%; EchoCare needed one state-wiring fix; EchoForge had the backend logic but no UI control to reach it.
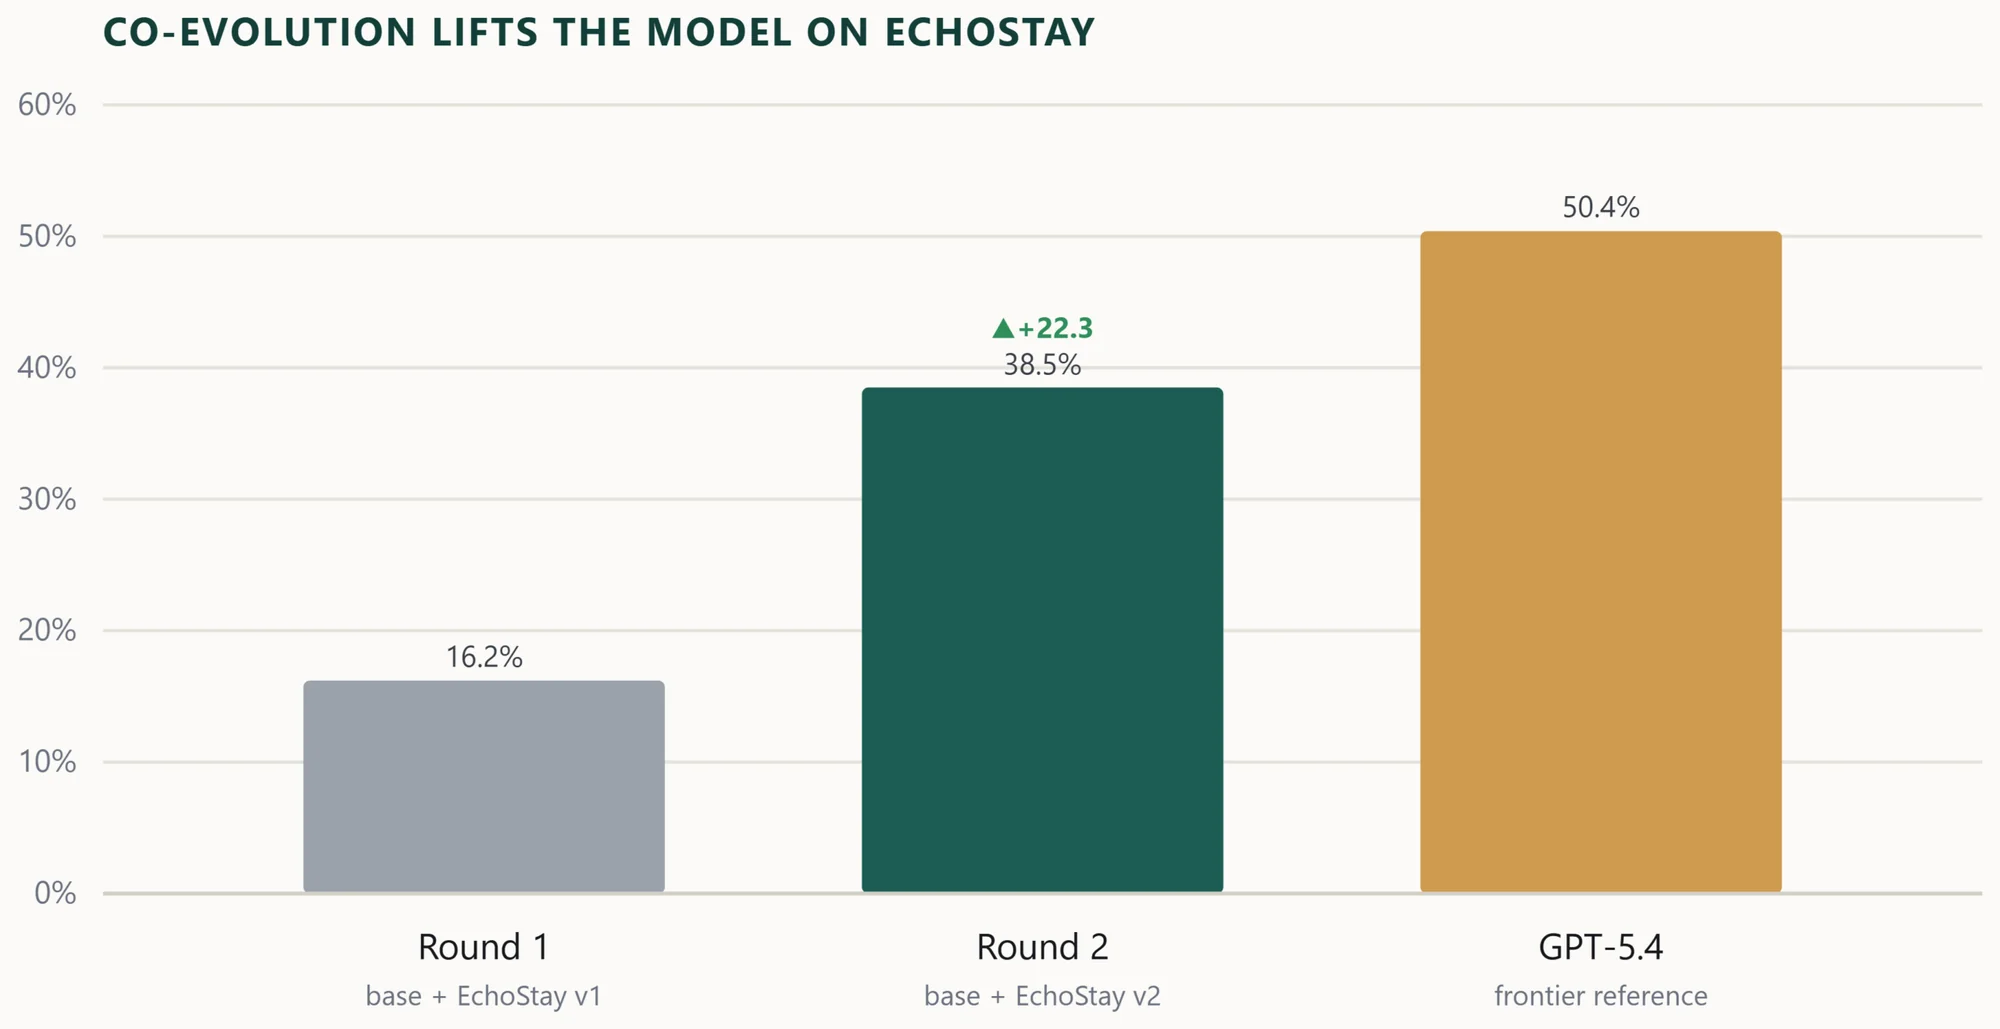
As the world sharpens, the model climbs with it. Re-running the loop on EchoStay across two rounds, the model trained on its corpus more than doubles, from 16.2% to 38.5%, two-thirds of the distance to GPT-5.4’s 50.4%. The model is not the only thing that learns; it is the thing that compounds once everything under it learns.
Figure 11: Co-evolution lifts the model on EchoStay. As the world went from v1 to v2, the model trained on it more than doubled, from 16.2% to 38.5%, a separate measure from the world’s own solve rate. Higher is better.
That boundary between repairing the world and teaching the model is easy to hold inside a controlled environment, where both are inspectable. The live web erases it: there is no world to repair mid-task, so when an action lands on nothing, correctness rests entirely on the agent noticing and choosing differently. That is the last thing a world has to teach, and where the live web is least forgiving.
From SFT to RL: Turning worlds into RLEs
Every result so far comes from imitation: the 9B model copies the trajectories GPT-5.4 got right. Imitation inherits a ceiling, though: a clean demonstration never shows how to recover from a mistake or when to stop, the failures that break agents in the wild. Reinforcement learning optimizes the outcome we grade and lets the model learn from its own trajectories, not a teacher’s.
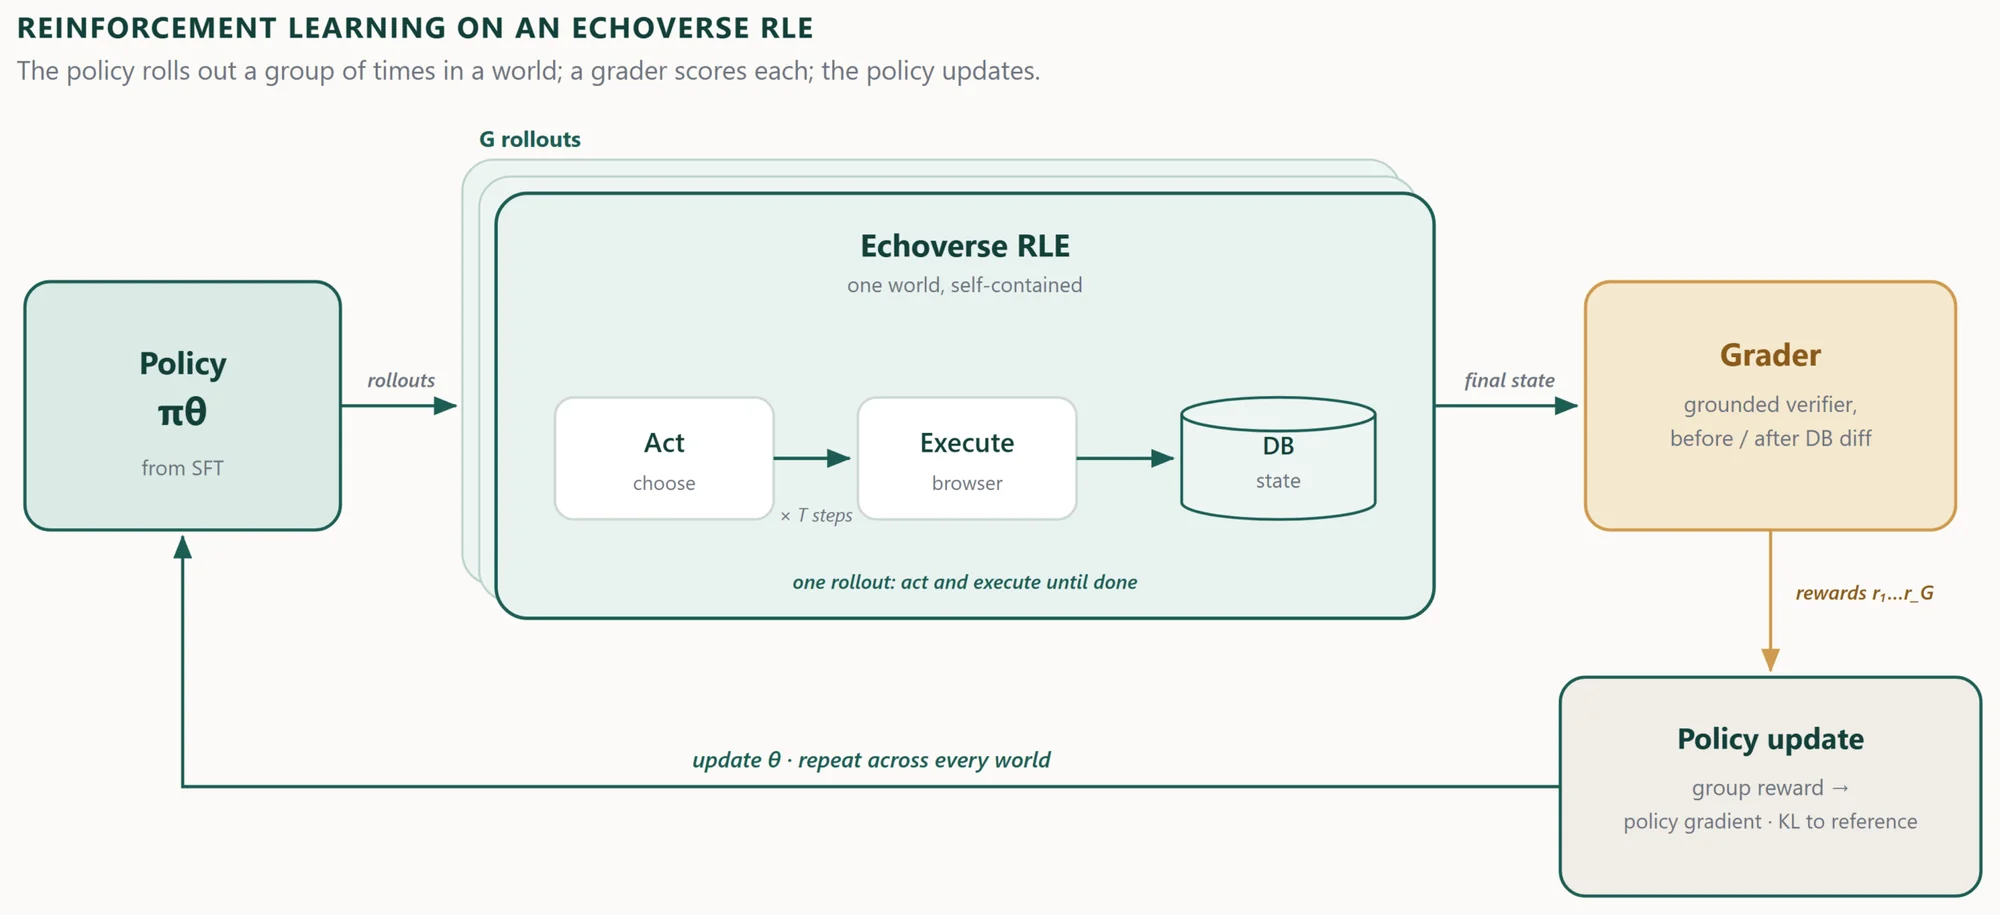
But reinforcement learning needs an RL environment (RLE) it can drive at scale. Each rollout needs a reset to a known state, throughput to sample in parallel, and a reward it can trust, and a run replays the same task thousands of times. The live web is not an RLE: it will not reset, so no two rollouts begin alike; it throttles and blocks automated traffic well before RL’s scale; and it exposes no ground truth, only a screenshot a second model must judge, so the reward is as noisy as the judge and a policy learns the judge’s blind spots rather than the task. Echoverse is an RLE by construction. Every world is a self-contained app we snapshot and reset per rollout, run in parallel, and grade from its own database, so the verifier that filtered the SFT data returns a grounded, verifiable reward rather than one inferred from pixels. The same worlds that benchmark an agent train one.
Figure 12: Reinforcement learning on an Echoverse RLE. From the SFT policy we roll out a group of trajectories in one world; each is a sequence of act and execute steps that changes the database. A grader, the same grounded verifier that filtered the SFT data, sits outside the environment and scores each rollout’s final database state into a reward. The group of rewards updates the policy, and the loop repeats across every training world.
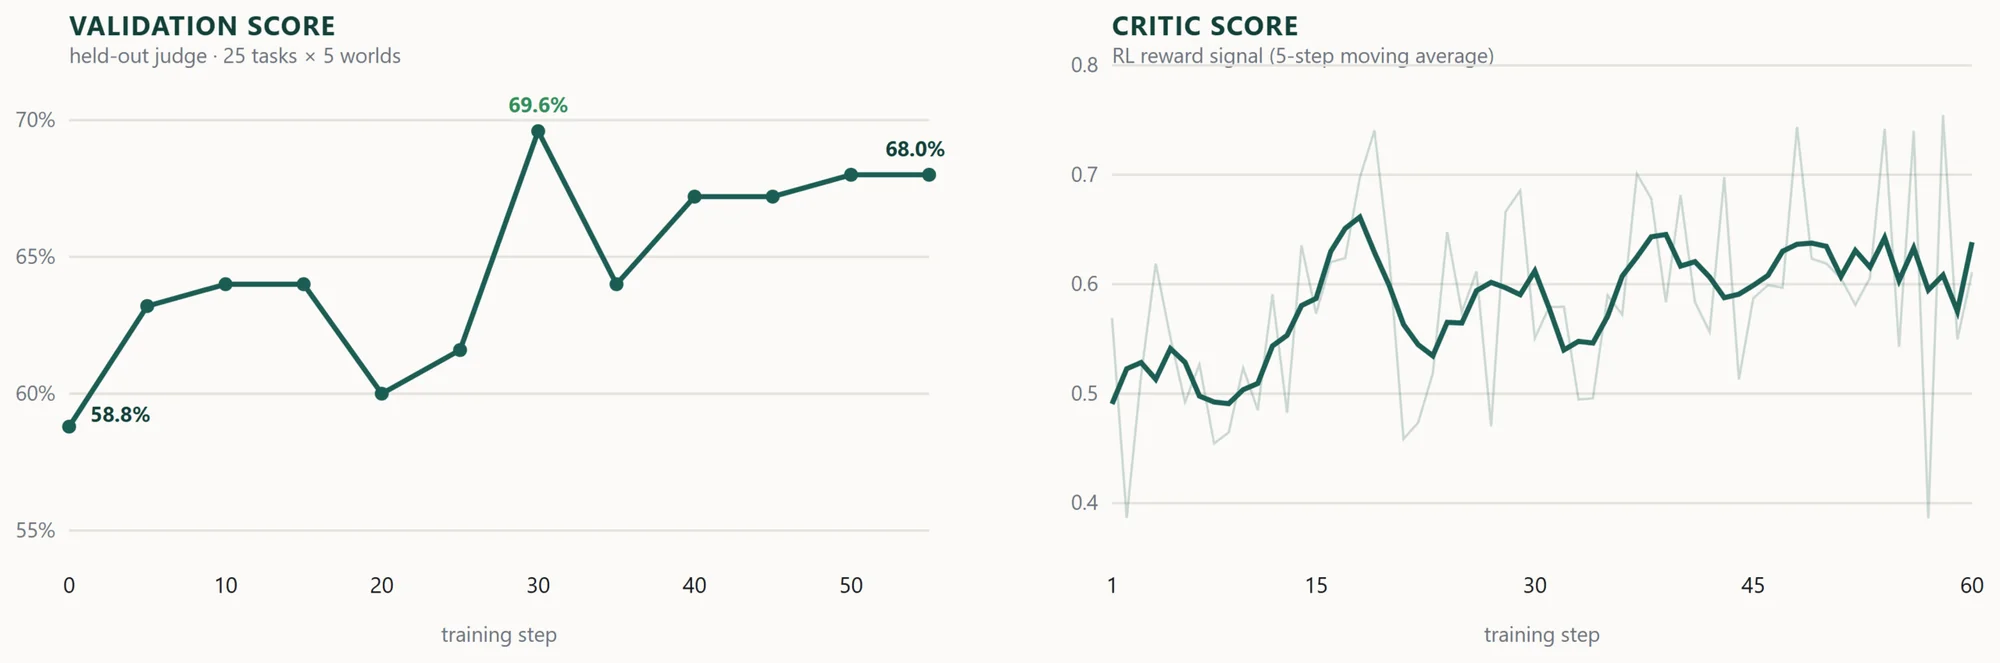
We take the SFT model as the starting policy and run RL against five worlds: EchoBank, EchoForge, EchoForum, EchoStay, and EchoTunes. Tasks come from the harder end of each world, where the SFT policy still leaves headroom, and each update draws on several graded rollouts. Each rollout earns two rewards: a trajectory reward from our database-grounded verifier (LLM judge GPT-4.1), and a dense per-step reward from a multimodal judge that grades each screenshot (GPT-4.1 vision). We train on roughly 100 tasks per world beyond the SFT data, for two epochs. On a held-out set of 25 tasks per world, the judged score rises from 58% to 69%. The teacher taught it what to do; the world taught it when to stop, when to recover, and when to give up.
Figure 13: Reinforcement learning on five worlds, over twoepochs. Left: the held-out judge score (25 tasks per world) climbs from 58% to 69%. Right: the critic’s mean score, the RL reward signal, trends up through training. The reward sums a trajectory reward from our database-grounded verifier (LLM judge GPT-4.1) and a dense per-step reward from a multimodal judge (GPT-4.1 vision).
Where this leaves us
A world is no longer a fixed benchmark you score against; it is a training surface you keep improving, where the same graded run that measures the model also sharpens the world that judged it. Deep worlds transferred where shallow clones pulled capability down; one widget rebuilt in a hundred forms taught a skill that reached the live web; co-evolution moved both sides at once; and reinforcement against the same worlds pushed the agent past imitation, lifting held-out performance and trimming wasted steps.
The durable advantage is not the largest inventory of synthetic websites. It is a factory that diagnoses what an agent cannot yet do, builds or repairs the world that teaches it, protects the capability already earned, and runs the loop again. The next turns scale three fronts at once. First, more deep worlds for the closed domains public benchmarks cannot reach. Second, more capability worlds for the interactions models keep failing. And, above all, more reinforcement against those grounded worlds: longer runs, harder tasks, and wider reward exploration that push the agent’s behavior and its performance further than imitation ever could. The levers compound: deeper and broader worlds make stronger RL, stronger RL boosts the agent, and every round exposes the next capability to build.
We are releasing a piece of the factory: environment code and graded test tasks for four worlds, two deep domains (EchoStay and EchoForge) and two capability worlds (the datepicker and nested-filter, each with an in-distribution and a held-out split). Every task carries the database-grounded verifier that scores it, so the same worlds can benchmark an agent or train one. Code and tasks: https://aka.ms/echoverse
When worlds grow at the frontier of an agent’s competence, evaluation stops being a scoreboard and becomes the engine that decides what to build next: worlds that keep learning alongside the agents they train.
Acknowledgments
We thank Alexey Taymanov, Andrew Zhao, Aravind Rajeswaran, Corby Rosset, Hussein Mozannar, Luiz Do Valle, Sara Abdali, Spencer Whitehead, Vibhav Vineet, Zach Nussbaum, Yadong Lu, Pashmina Cameron, Rafah Hosn, and Chinmay Karkar for their valuable help, insightful discussions, and continued support throughout this work.
The source text above remains the property of its publisher and is reproduced for commentary.