Anthropic released Claude Fable/Mythos 5.1 on 1 September 2026, reporting 52.6% on Terminal-Bench-Science 0.1 versus 24.7% for Fable 5. A launch-day visual-coding evaluation across reasoning levels shows Fable 5.1's best pelican SVG only at maximum effort, at 65,927 output tokens, 13 minutes 54 seconds, and $3.30; low/medium effort skipped visible reasoning on that simple prompt. Listed token prices are unchanged, but cache-read prices fell 75%; Artificial Analysis measured roughly 1.7x output-token growth and about 20% higher cost per task at maximum. The release therefore raises the capability ceiling while increasing the cost of operating at that ceiling.
Anthropic released Claude Fable 5.1 and Claude Mythos 5.1 on 1 September 2026, with Fable 5.1 positioned for coding, knowledge work, and long-running problem-solving tasks. The headline official metric is a 52.6% score on Terminal-Bench-Science 0.1, a benchmark announced on 27 August, versus 24.7% for Fable 5, 29.0% for Opus 5, and 22.4% for GPT-5.6 Sol.12
Context
Simon Willison's launch-day probe changes the frame from official scores to the pelican benchmark, a text-to-SVG prompt used to gauge visual coding judgment. Fable 5.1 has five reasoning levels with no no-reasoning option; on this prompt, low and medium produced no visible reasoning and about 1,977-1,998 output tokens, high produced a short planning trace, while xhigh and max used 36,767 and 65,927 output tokens respectively. Max yielded the best pelican the author reports having seen from an Anthropic model.1
Assessment
Economic reporting moves the analysis beyond a single image. Per-token list prices are unchanged from Fable 5, but cached prompt reads fell 75% to $0.25 per million tokens; Artificial Analysis nevertheless observed about 1.7x output-token growth and a net task-cost increase of about 20% at max. On the visual task, that overhead maps to $3.30 for one simple SVG at max versus about 10 cents at low/medium, so the science-benchmark gain does not automatically translate to cheaper agentic use.12
Caveats
AI hypothesisThe available record is launch-day. The primary source is one visual prompt using an idiosyncratic benchmark, and the secondary source includes system-card excerpts and social media reports rather than peer-reviewed evaluation. Artificial Analysis' independent run included about 4% fallback to Opus models, and the hypothesis that Fable and Mythos share weights with different routing is explicitly unverified. The science conclusion would be threatened by replication failure on a public Terminal-Bench-Science harness; the visual-benchmark conclusion would need many prompts before grounding cost-effectiveness claims.12
Cross-source check
2 sources
Agreed
Anthropic launched Claude Fable 5.1 and Claude Mythos 5.1 on 1 September 2026 as new flagship coding/knowledge-work models.Simon WillisonLatent Space
Both sources report Fable 5.1 scoring 52.6% on Terminal-Bench-Science 0.1, more than double Fable 5's 24.7%.Simon WillisonLatent Space
Reported by one source only
Simon Willison's pelican evaluation reports that Fable 5.1 at low and medium reasoning produced no visible reasoning trace and about 1,977-1,998 output tokens, while xhigh and max consumed 36,767 and 65,927 output tokens and cost $1.83 and $3.30 respectively; the max result was judged the best pelican from any Anthropic model.Simon Willison
The animated pelican in the primary source was produced by piping the completed max-effort SVG into a high-effort continuation call costing $1.37, not by another max-effort generation from scratch.Simon Willison
Anthropic cut cache-read pricing from $1.00 to $0.25 per million tokens, a 75% reduction, while keeping list input/output/cache-write prices unchanged at $10/$50/$12.5 per million tokens.Latent Space
Artificial Analysis measured about 1.7x output-token growth for Fable 5.1 and a net task-cost increase of about 20% over Fable 5 max, with Fable 5.1 max costing $3.76 per task on its index; the 75% cache cut saved about $1.40 per task.Latent Space
Artificial Analysis' evaluation used Anthropic's server-side safety routing, with about 4% of output tokens served by fallback models, and unverified community analysis claimed Fable and Mythos 5.1 share the same weights with different safeguard routing thresholds.Latent Space
Claude Fable 5.1 made me a really nice animated pelican
1st September 2026
Today is Claude Fable (and Mythos) 5.1 day. Anthropic say that Fable 5.1 “sets a new standard for coding, knowledge work, and long-running problem-solving tasks”. Their announcement spends a notable amount of time on scientific research, boasting of a 52.6% score on the brand new Terminal-Bench-Science 0.1 benchmark (first announced on August 27th), up from 24.7% for Fable 5, 29.0% for Opus 5 and 22.4% for GPT-5.6 Sol. Other benchmarks show slightly improved scores, but none as impressive as the Science one.
But how well can it pelican?
Back in July I wrote about how I was losing faith in the pelican benchmark—its connection to how good the models were at other tasks didn’t seem to hold as strongly as it did back in 2025. The most interesting insights I get from it now are comparisons within model families, and particularly comparisons for the same prompt at different reasoning effort levels.
Fable 5.1 has five reasoning levels: low, medium, high, xhigh, max—and no option to turn off reasoning entirely.
I fixed an issue in llm-anthropic which caused reasoning traces not to be correctly recorded, then ran some prompts.
Here’s the full set of pelicans for all of the reasoning levels, each with the full reasoning transcript. I’ll replicate them here:
Low and medium, both without reasoning?
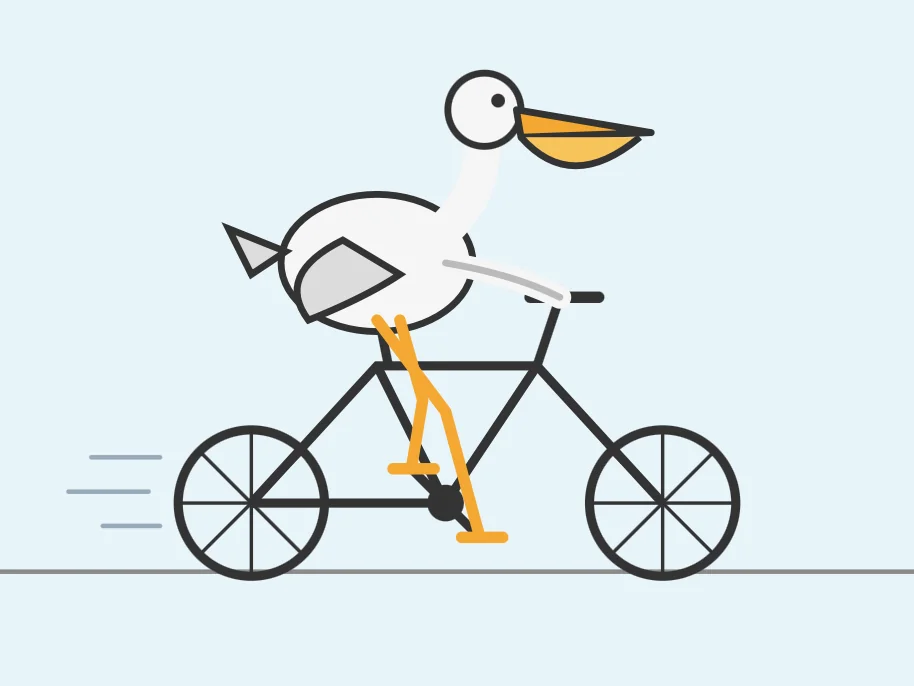
Next, a bit of a mystery. This is what I got for effort low :
The transcript doesn’t show any summarized reasoning tokens, and the output token count is 1,998. With Claude that output token count includes reasoning tokens. It took 23.8 seconds and cost 10.017 cents.
I bumped that up to medium and got this:
Weirdly, that one also shows no reasoning text and used 1,977 output tokens—21 tokens less than low . It took 23 seconds and cost 9.912 cents.
So for this particular prompt (“Generate an SVG of a pelican riding a bicycle”) Fable 5.1 appeared to skip reasoning entirely at both low and medium settings.
High
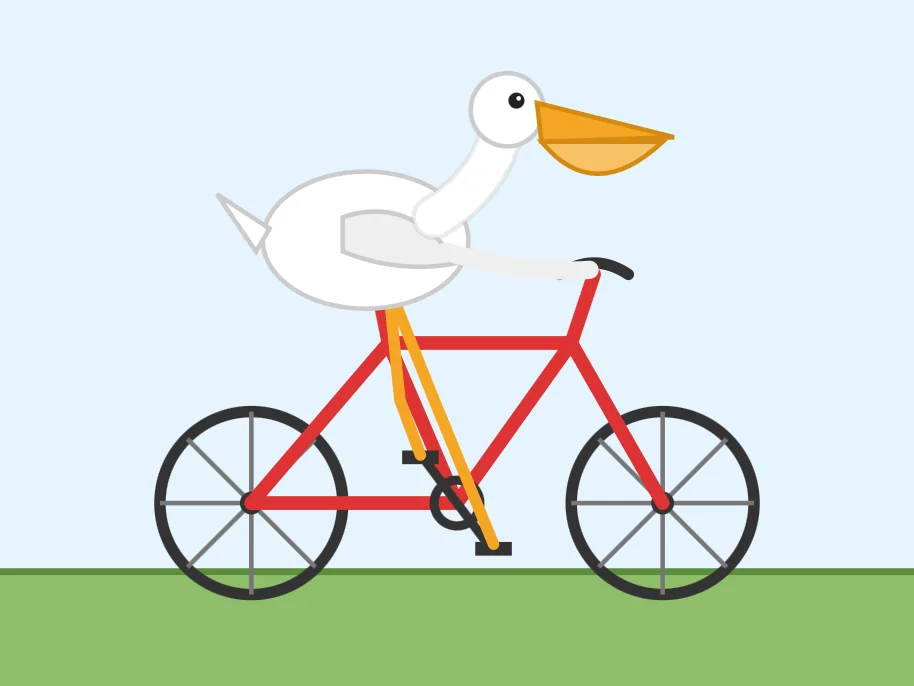
Here’s high —29.6 seconds, 2,612 output tokens, 13.087 cents:
This one did do a bit of reasoning, summary here:
I’m planning the SVG layout for a pelican riding a bicycle, with a sky and ground background, a bicycle with two spoked wheels, frame, seat and handlebars, and a white-bodied pelican with a long neck and orange beak positioned on top.
Really not much difference from low and medium , though.
Extra High
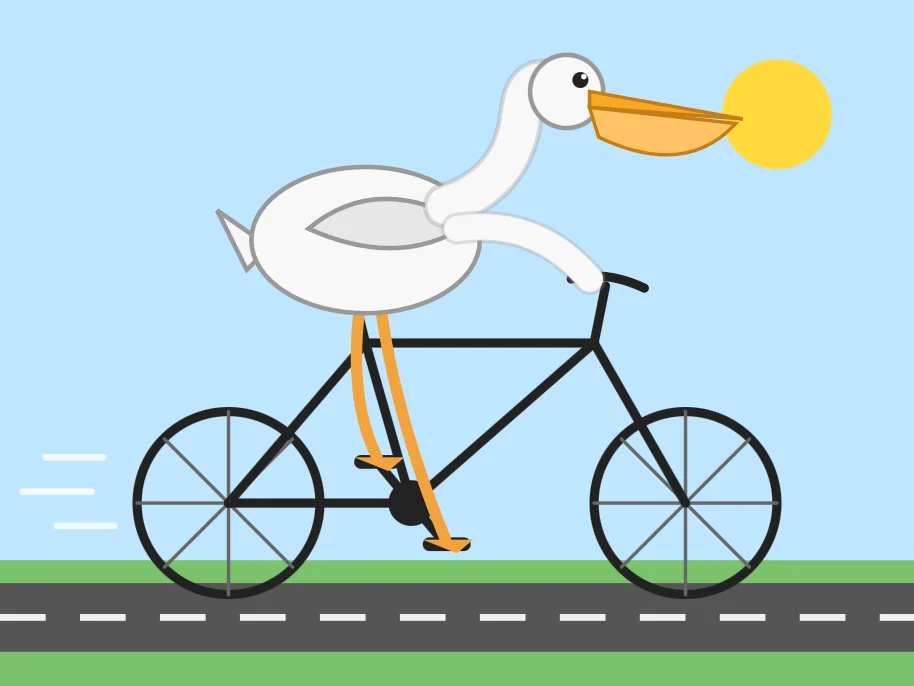
At xhigh things got radically different. 36,767 output tokens, 7 minutes 51 seconds, $1.83!
The reasoning trace is pretty lengthy, and includes details like this:
Adding the eye, wings stretching down to the handlebar grip, orange legs reaching to the pedals, and a small tail feather, while keeping the pelican intentionally oversized compared to the bike for comic effect. [...] I’ll accept the slight thickness as charming rather than overengineering it.
Max
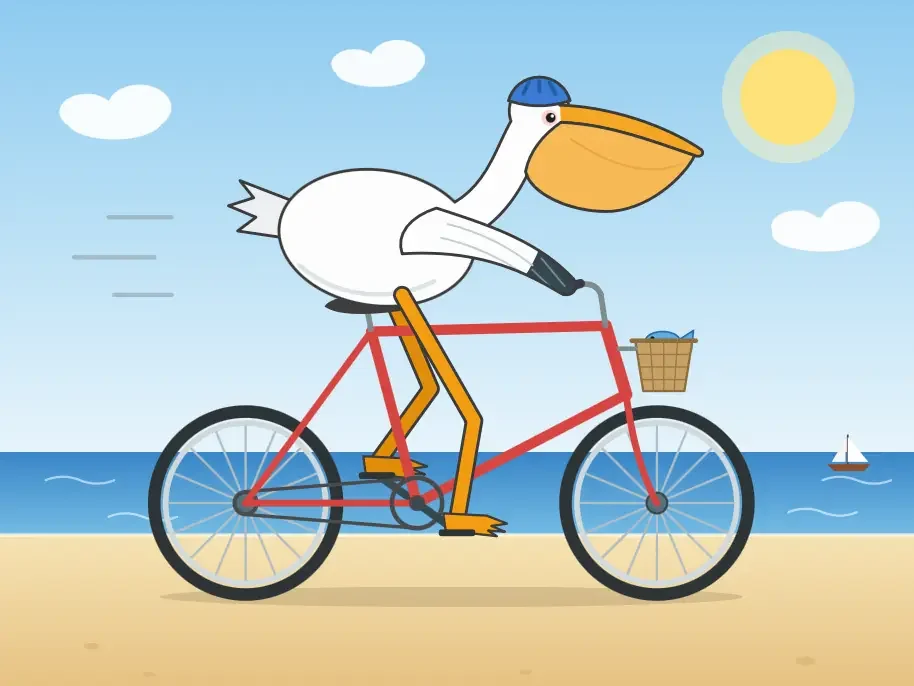
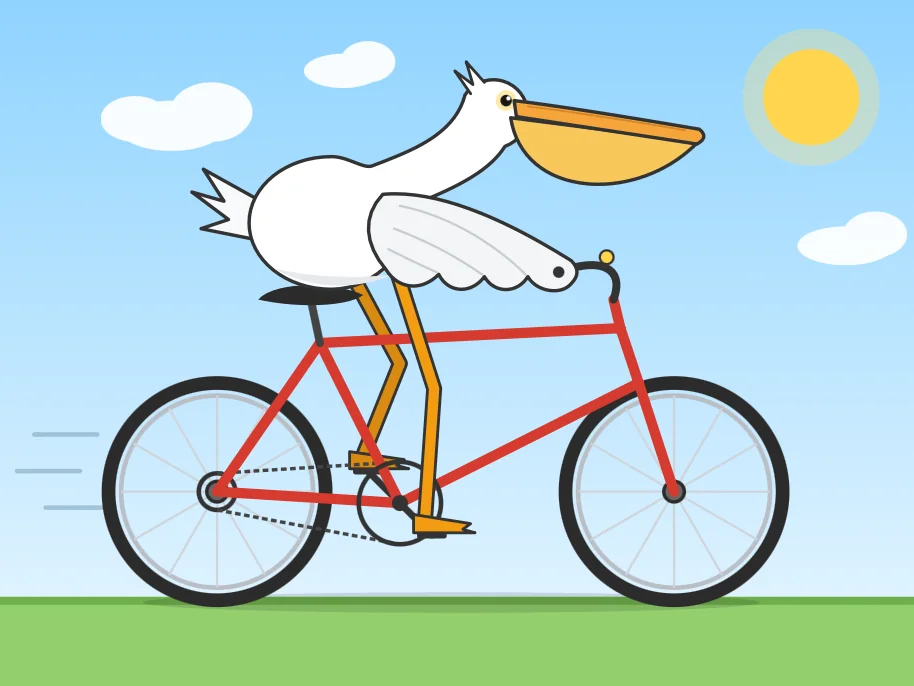
Setting effort to max gave me the best pelican I’ve seen from any of Anthropic’s models. 65,927 output tokens, 13 minutes and 54 seconds, $3.30:
There’s a lot to like about this. The background is tasteful, the legs are clearly on either side of the frame, the feet are on the pedals, the wing is on the handlebars, the pelican has a cute blue hat and there’s a basket with a fish.
It’s still not showing nearly the same level of flair as Gemini 3.7 Flash, but I didn’t ask for flair—I asked for an SVG, and that’s what I got.
Some highlights from that reasoning trace:
Adding pedal shapes near both feet, with the far foot on the second leg partially visible behind the frame. I’m considering whether to add a small scarf or cap for extra character, but leaning toward keeping it simple to avoid clutter. Now I’m debating a bicycle helmet on the head versus the pelican’s signature crest—the beak and pouch already read clearly as “pelican,” so a helmet could reinforce the bicycle theme without losing identity, though it might compete with the crest for visual space. I realize the beak at (484,84) would overlap with the dome helmet, so I need to shrink the helmet so it only covers the top of the head, adjusting its arc endpoints to sit higher and narrower so the beak can attach cleanly at the front without collision. [...] I’m adding a darker tip region to represent the primary feathers, then reconsidering the trailing edge to include scalloped feather curves instead of one smooth line for a more natural look. [...] Now I’m checking the vent line placements on the helmet, making sure they sit far enough inside the helmet’s edge given the stroke width and rounded caps, and confirming each vent stays within the helmet’s circular boundary. [...] I decide skipping a handlebar bell and tire highlights since they’re unnecessary additions. Now I’m reconsidering the front fork’s curve — the current control point pulls the shape backward when it should bow forward for a proper rake, so I need to shift the control point rightward to fix the fork’s lean.
OK, let’s animate it
On Hacker News, swalsh commented on that Max pelican:
Now that it’s a solved benchmark, can we get the animated version?
I didn’t want to spend another $3 so I took the Max pelican and piped it into the default thinking level of High:
6,121 input, 26,201 output = $1.37. The result looked like this, exported here as video since some people have trouble viewing animated SVGs:
The wheels in the video are rotating in the wrong direction, but I think that’s an artifact of the conversion to MP4—they seem to be going in the correct direction in the original SVG.
The source text above remains the property of its publisher and is reproduced for commentary.
Comprehensive AI news roundup of Claude Fable/Mythos 5.1's launch, including benchmark highlights, 75% cache-read price cut, community reactions, and deployment caveats.