Simulation as the New Scaling Law: Simile's $2B Bet and the Synthetic Human Subject
Simile AI's $2B Series B and AINews' stage analysis jointly argue that human simulation has become the latest load-bearing component of AI pipelines, replacing focus groups and A/B test panels with post-trained digital twins. The central evidence—digital twins reproducing human responses at 85% of test-retest reliability—is real but self-reported and not yet independently validated.
The event is the consolidation of human simulation as a commercial scaling law: Simile AI's $2B Series B and the coverage framing it as the moment the 'human subject'—focus groups, user studies, A/B test panels—becomes an inference workload. The new claim is not that agents can pretend to be people, but that post-trained digital twins can stand in for real populations at commercially relevant fidelity.12
Context
Both documents trace the lineage from the 2023 Smallville generative agents paper to simulations of 1,000 people and then to Simile. AINews places this as stage seven of a longer pattern: reward models, synthetic corpora, distillation, self-curricula, automated research, and synthetic environments all flipped from human-made to model-made before the human subject did. What changed is that the remaining bottleneck in this trajectory is no longer generation quality but verification.12
Assessment
The constraint shift is from model capability to data and verification. Simile's differentiator is post-training on interviews, transactions, and registered RCTs to recover human bias, inconsistency, and causal texture that frontier 'agent models' optimize away. The credible version of the claim is that the binding constraint for replacing human subjects is not how realistic the generation looks, but whether the synthetic population can be trusted—hence the emphasis on registered RCTs as a verification mechanism.12
Caveats
The evidence base is thin for the headline numbers. The 85% figure compares digital twins to humans' own two-week test-retest reliability, not to ground truth about future behavior; the '10% worse, 100x cheaper, 10000x faster' trade-off is a slogan without a published methodology. No independent evaluation of Simile's Fortune 100 results is provided. I would revise the assessment if a blinded, preregistered study showed simulated populations predicting consequential decisions—purchases, votes, dropout—better than a random human panel at comparable cost.12
Cross-source check
2 sources
Agreed
Simile's digital twins of 1,000 people, built from two-hour biographical interviews, reproduced their source humans' survey and behavioral responses at 85% of the humans' own test-retest reliability.Latent SpaceLatent Space
Frontier LLMs are poor simulators of real human behavior because they are optimized toward rational/agentic responses; Simile therefore post-trains on interviews, transaction data, and registered RCTs to recover human bias and causal texture.Latent SpaceLatent Space
The work descends from the 2023 Smallville/Generative Agents paper, through generative agent simulations of 1,000 people, to Simile.Latent SpaceLatent Space
Simulation is framed as a cheaper and faster substitute for human research panels such as focus groups, user studies, and A/B tests.Latent SpaceLatent Space
Reported by one source only
Simile raised a $2B Series B from GreenOaks and Index Ventures, with Fei-Fei Li and Andrej Karpathy as backers, and runs tens of millions of simulations for Fortune 100 clients including CVS.Latent Space
Simile's long-term ambition includes simulating all 8 billion people to study climate change, democratic instability, and UBI.Latent Space
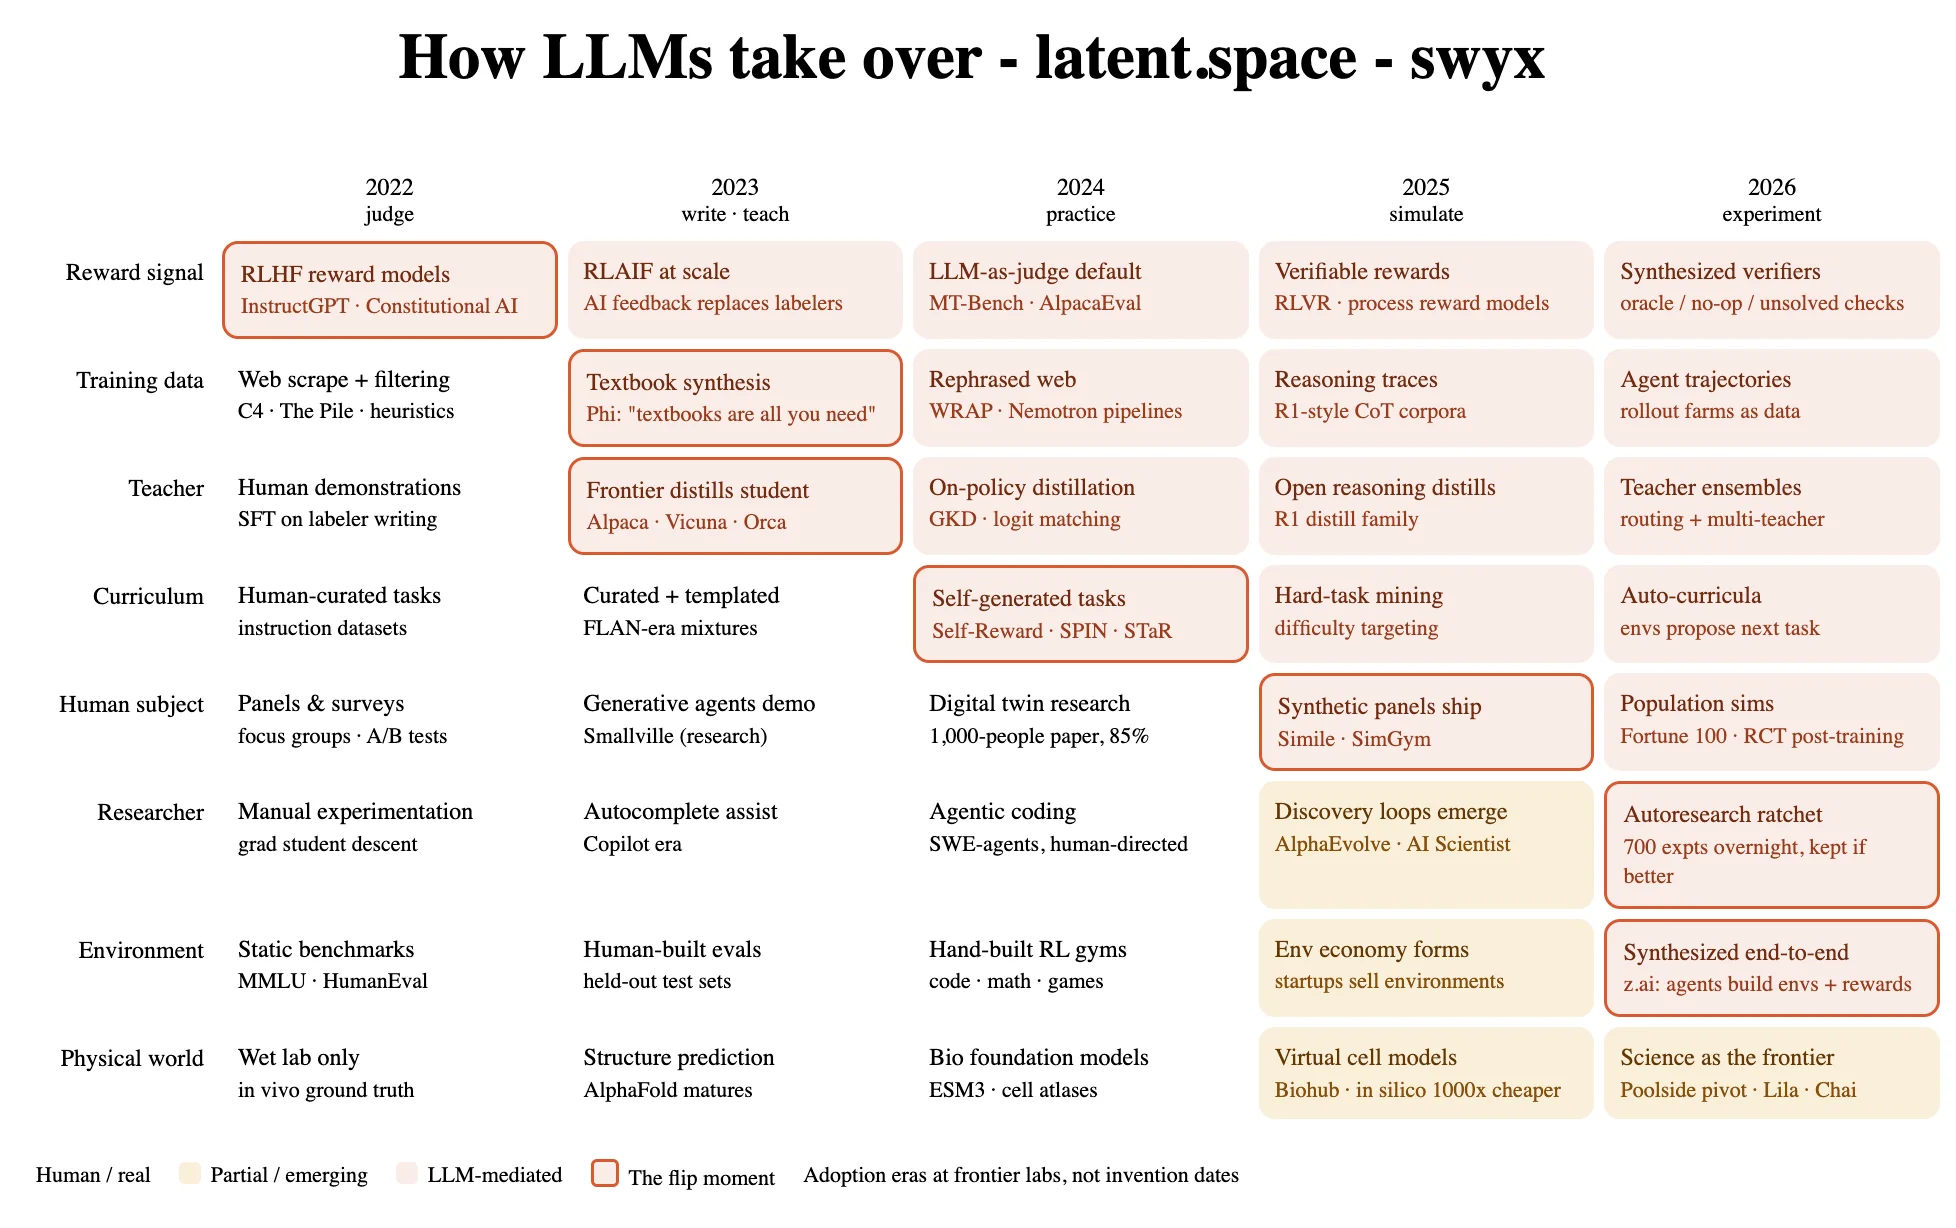
The article proposes an eight-stage chronology in which reward signals (2022), training data (2023), teachers (2023), curricula (2024), researchers (2026), environments (2026), human subjects (2025), and the physical world (2026) each flipped from human-made to model-made.Latent Space
Current applications of human simulation include SimGym at Shopify for shopper trajectories and Tencent's billion-persona approach.Latent Space
The synthetic frontier is argued to advance when verification improves, not when generation improves, with registered RCTs for Simile and oracle/no-op checks for Z.ai verifiers as examples.Latent Space
By AI standards today is a pretty quiet Friday, so it’s time to take a step back and reflect on what is really going on. If you read our 2025 reading list, and followed our coverage of Z.ai GLM, understood the Poolside pivot, been following our AI for Science themes, and tuned in to today’s Simile pod, you not only are one of the biggest readers of Latent Space, you will probably also arrive at this mental model:
Every year since 2022, one more component of the pipeline that produces machine intelligence has flipped from human-made to model-made. Not gradually, and not evenly — each flip has a patient zero, a paper or product where the synthetic version first became load-bearing at a frontier lab, and from there on, the future is simply here but not yet productionized.
And if you squint, what we used to call “synthetic data” and “synthetic rubrics” and “AI researcher” and “end to end RL environments” is just increasingly ambitious human simulation - 10% worse, but 100x cheaper and 10,000x faster.
Stage 1: The reward signal (2022)
The first thing to go synthetic was, counterintuitively, the judge. InstructGPT established the now-canonical trick: collect human preferences once, train a reward model, and let the policy optimize against the model rather than the humans. From the policy’s point of view, the thing dispensing approval was already an LLM. Constitutional AI pushed further and had the AI critique itself against a set of principles (RLAIF), and Lee et al. later showed AI feedback matching human feedback at a fraction of the cost. By the time LLM-as-judge became the default eval methodology (MT-Bench, AlpacaEval), the entire approval apparatus — reward, critique, evaluation — ran on models judging models.
Stage 2: The training data (2023)
Microsoft’s Phi series made the argument in its title: Textbooks Are All You Need. A small model trained on LLM-synthesized, textbook-quality data punched far above its parameter count, and phi-1.5 confirmed it wasn’t a fluke. Apple’s WRAP generalized the move: don’t just generate data, rephrase the entire web with an LLM, and pretraining gets roughly 3x more efficient. From there the pipeline industrialized — NVIDIA’s Nemotron-4 340B shipped with a permissively licensed synthetic data generation pipeline as a headline feature, and by 2025 reasoning-trace corpora (chains of thought generated by strong reasoners) had become a standard pretraining and mid-training ingredient. The corpus, the thing that was supposed to be the irreducibly human input, was now substantially model-written.
Stage 3: The teacher (2023)
Weeks after ChatGPT’s API opened, Stanford’s Alpaca demonstrated that a $600 fine-tune on GPT-generated instructions could clone much of a frontier model’s behavior. Vicuna did it with shared conversations; Orca did it with rich teacher explanations rather than bare answers. The technique matured from imitation into a proper training discipline — on-policy generalized knowledge distillation fixed the train/inference mismatch — and reached its cultural peak when DeepSeek-R1 shipped a family of distilled models alongside the flagship, making “the teacher is a model” the default assumption for every small model release since.
Stage 4: The curriculum (2024)
Stages 1–3 made the inputs synthetic; stage 4 is where the loop starts closing on itself, because the model begins deciding what to learn next. The pieces existed early — Self-Instruct (models writing their own instruction sets) and STaR (models bootstrapping their own reasoning traces) are both 2022 — but the flip came when Meta’s Self-Rewarding Language Models and SPIN showed a model could generate its own tasks, judge its own outputs, and improve past the ceiling of its human preference data. Curriculum design — historically the most artisanal part of ML, the taste-driven choice of what to train on next — became something models do to themselves.
Stage 5: The researcher (2026)
The assistance era (Copilot, then SWE-agents) kept a human choosing the experiments. The discovery era did not. DeepMind’s AlphaEvolve evolved genuinely new algorithms in 2025, and Sakana’s AI Scientist (now in Nature!) sketched the full paper-writing pipeline. The big moment was Karpathy’s autoresearch in March 2026: a deliberately minimal ratchet loop where a coding agent modifies a real LLM training setup, runs a five-minute experiment, keeps the change only if validation loss improves, and repeats overnight. His own extended run stacked 700 experiments into 20 kept improvements, cutting time-to-GPT-2 from 2.02 to 1.80 hours — real, transferable code changes found while he slept.
Stage 6: The environment (2026)
RL’s scaling bottleneck moved from the model to the environment: you need thousands of executable, verifiable, professionally realistic task worlds, and humans can’t hand-build them fast enough. We covered this recently in our z.ai / GLM-5.3 issue: Z.ai built pipelines that synthesize environments end to end — research agents mine real work patterns and convert them into long-horizon environments with hidden state, a judge agent attempts each task to confirm it’s solvable, and verifiers are synthesized without seeing the reference solution, then stress-tested with oracle, no-op, and unsolved-state checks until their binary reward is reliable enough to train on directly. As the GLM-5.3 release puts it, the entire environment, judging, and verification stack is synthetic all the way down. The same week, Ornith-1.5 shipped claiming end-to-end self-improvement — the model proposes its own tasks and generates its own RL rollouts. The gym, the referee, and the scoreboard are all models now.
Stage 7: The human subject (2025)
If models can be the judge, teacher, and environment, the remaining human role in the loop is subject — the source of preferences, behavior, and demand. That’s the layer Simile is replacing. The lineage runs from Joon Sung Park’s Generative Agents (Smallville, 2023) through Generative Agent Simulations of 1,000 People, where digital twins built from two-hour biographical interviews reproduced their source humans’ survey and behavioral responses 85% as accurately as the humans reproduced themselves two weeks later.
The big hurdle to overcome: frontier models are trained toward being agent models, which makes them bad simulations of real people — so Simile post-trains on interviews, transaction data, and registered RCTs from the Open Science Framework specifically to recover human bias, inconsistency, and causal texture, and reports early scaling laws for simulation quality. With SimGym at Shopify simulating shopper trajectories and Tencent’s billion-persona approach at the crude end of the spectrum, the focus group, the user study, and the A/B test panel are becoming inference workloads.
Stage 8: The physical world (2026, in progress)
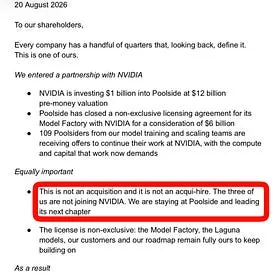
The last row of the grid never quite turns red, and that’s the point. Poolside’s reverse-execuhire letter drew the line precisely: the world’s problems split into intelligence-bound ones (solvable by scaling cognition, soon commoditized by open weights) and experiment-bound ones, where “no amount of intelligence substitutes for real-world experimental feedback — 100,000 brilliant minds won’t cure cancer without a wet lab.” Their bet is that AI’s durable value accrues to whoever owns the experimental loop: AI as “the world’s most valuable scientific discovery engine.”
The bio side is running the same play from the other direction. CZ Biohub is imaging the Human Cell Atlas into a virtual cell — because in silico is roughly 1000x cheaper and faster than in vivo — and extending toward a virtual immune system, with Chai, Xaira, and Lila’s data-center-shaped labs filling in the AI-for-science stack. The physical world is the one component that can’t be fully synthesized — only compressed, cell by cell, into models.
[AINews] Poolside gets $12B reverse-execuhire to NVIDIA; founders stay for $1B, employees go for $6B, Infraco scaling to 7GW neocloud
The exponential starts at the diagonal
Read the grid one more time and a second pattern appears underneath the first. Every flip was preceded by the same objection — model collapse, hallucination stacking, garbage in garbage out — and every flip happened anyway, at the exact moment a verification mechanism made the synthetic version trustworthy: aggressive filtering for Phi’s textbooks, judge-vs-judge agreement studies for LLM evals, unit tests and proof checkers for RLVR, oracle/no-op checks for z.ai’s verifiers, registered RCTs for Simile’s twins, the wet-lab loop for the virtual cell. The synthetic frontier doesn’t advance when generation gets better. It advances when verification does.
Which suggests where it goes next. The gray triangle remaining in the bottom-left of the grid — physical experiment, embodied ground truth — is exactly the region where verification is slowest and most expensive. The models learned to write, then to judge, then to practice, then to experiment. The remaining question of the decade is how much of reality they’ll need to touch — and how much they can get away with simulating.
10% worse, 100x cheaper, 10000x faster… and improving on ALL three dimensions fast.
One more time, with feeling:
AI News for 8/20/2026-8/21/2026. We checked 12 subreddits, 544 Twitters and no further Discords. AINews’ website lets you search all past issues. As a reminder, AINews is now a section of Latent Space. You can opt in/out of email frequencies!
AI Twitter Recap
Stealth Models, Chinese Frontier Pressure, and DeepSeek’s Multimodal Push
Ox Alpha became the day’s central mystery model: multiple builders reported unusually strong coding and agentic performance, with speculation converging on a Zhipu/GLM-family model—possibly GLM-5.3 Vision or a flash variant rather than a giant new base model. Reports included Theo saying it was “slaughtering” internal benchmarks, later merging 8 PRs based on its approval, and Kimmonismus citing >80% on 10 DeepSWE tasks vs 65% for Fable and 52% for GPT-5.6 Sol. Community distribution happened quickly via Hermes Agent/OpenCode/OpenRouter and Cline.
The strongest technical read from the crowd was “post-training + infra > sheer size”: several independent takes argued Ox Alpha’s speed profile and style looked more like an efficient GLM derivative than a 1T+ monster. See Tim Dettmers on faster output / weaker partial prefill suggesting fewer active params, scaling01 arguing it may be a bigger teacher distilled into 5.3-class models, and teortaxesTex repeatedly narrowing toward GLM-5.3/5.4 Vision. That interpretation fits the broader thesis from a detailed GLM-5.3 analysis: gains came from the same 743B base as GLM-5.2, with improvements attributed to scaled post-training, better sandboxes, and SAO for finer credit assignment in long-horizon agent tasks, summarized in ZhihuFrontier’s thread.
DeepSeek shipped the day’s most concrete release: DeepSeek-V4-Flash-Vision-Exp adds multimodal support while reportedly preserving V4-Flash text capability, with DeepSeek claiming multimodal-agent performance close to Opus-4.8. The rollout includes mixed text+image API support with 117–384 image tokens billed at Flash pricing and a new Files API for reusable uploads. This appears to have resolved at least part of the Ox Alpha confusion, with observers noting the mystery model had likely been a “blinded VLM” in some tests.
Broader signal: Chinese labs are compressing the frontier on both price/perf and multimodal agents. That was reinforced by Kimmonismus arguing a rumored GLM-5.3 Flash-class Ox Alpha would force reactions from US labs, and by SemiAnalysis asking directly whether open models are catching up.
OpenAI, Codex, and Pricing/Usage Economics
OpenAI cut GPT-5.6 Sol pricing by over 20% for three months in the API and credit-based products, announced by @OpenAI and @OpenAIDevs. This stacks with product-level promotions like Code’s 50% discount through Sept. 3 and Cognition’s note that on Devin, Sol is now effectively 76% off list through Oct. 3 after combining discounts. The move reads as both a utilization/efficiency update and a competitive response to cheap Chinese inference.
Codex usage appears to be exploding: thsottiaux said Codex hit 20M active users and granted all Codex and ChatGPT Work users a “banked reset”, quickly amplified by Theo and Kimmonismus. There were also anecdotes of the product exceeding expected limits, e.g. Theo claiming a long-running goal consumed ~$800 in tokens after he’d already hit 0% remaining.
OpenAI added better spend controls: teams can now track usage and spend by API key and set hard monthly org/project limits, useful as agentic workloads become less predictable and more concurrent.
Market sentiment shifted back toward OpenAI in startup tooling: immad suggested Anthropic’s startup share may have peaked in Q1, with Sol and Codex “turning the tide back”. In parallel, some users framed Sol as the current best all-around model for coding/math/agentic tasks, e.g. DimitrisPapail’s “most capable model available for almost every task” take.
Agents, Harnesses, and the Shift Toward Environment-Centric Training
The center of gravity is moving from prompts to environments: the most substantive thread here was again GLM-5.3’s sandbox-scaling interpretation: same base model, but better long-horizon performance from richer executable environments and SAO-style counterfactual credit assignment. This aligns with other work shared today: Google’s EnvHarness / EnvRigger adapts static environments using a plugin layer and policy-diagnosed reshaping, improving held-out performance by up to 9 points with 9.8% fewer execution steps.
Benchmarks are getting more task-specific and harder: FACET creates executable terminal tasks from agent skills and validated 6,078 tasks; SWE-bench Science introduces 119 scientific software tasks where even Claude Code + Opus-5 is under 50% pass@1; CADBench finds top models at only 24.6% pass rate across realistic Fusion 360 tasks; and AI4AI-Bench tests recursive self-improvement over 10 research repos, with the best model only at 0.288 average score.
Agent infra is getting more productized: GitHub rolled out collaborative agent workflows into Slack and Teams, with Slack describing Devin-like flows where the agent picks up tasks, opens PRs, and loops in design inside the shared channel (example). There’s also continued work on agent runtimes: nac v0.1.3 added sandboxed git worktrees, session organization, and vision-aware image reading; Hermes Agent made Ox Alpha available and exposed “Blank Slate mode” plus automatic skill pruning; and OpenHands switched its free default to Kimi K3.
Inference-serving correctness in RL got an important systems result: vLLM’s IsoExec addresses rollout/training logprob mismatches caused by floating-point non-associativity, enforcing bitwise parity across TP/EP/SP layouts. On Qwen3.5-35B-A3B with DAPO on 8xH100, logprob diff reportedly dropped from 1.6e-2 to 6.7e-7 at 25.3% overhead.
Research Highlights: Routing, Recirculation, and Robotics
Inference-time architecture ideas: a DeepMind paper on Recirculation got attention for feeding contextualized deeper-layer activations back into earlier processing at inference time, without retraining. The summary cited improvements including -60% contextualization errors, -23% perplexity, and +21% GSM8K in reported experiments (thread).
Model routing got a more principled treatment: Pandora’s Router from Google DeepMind frames routing as an optimal search problem with costly inspection, rather than assuming routing estimates are free. The claim: it matches exhaustive-estimation quality while calling expensive estimators less often, including settings with specialist LLMs and variable inference-time reasoning.
Robotics had two strong updates: NVIDIA AVO reportedly solved all 183 levels across 25 public ARC-AGI-3 environments, though François Chollet cautioned this is the public demo/tutorial set rather than the full benchmark. Separately, Jim Fan introduced T-Rex, a tactile-reactive dexterous manipulation stack with asynchronous vision/tactile experts plus what’s described as the largest open tactile dataset yet: 50 hours / ~5,500 episodes / 22-DoF hardware.
Infrastructure, Compute, and Open Models
Open-model access and local inference continue improving: Ollama welcomed AT&T to open models and added Kimi K3 to Pro/Max subscriptions. Yuchen Jin highlighted UC Berkeley’s FreeToken: 753B GLM-5.2 at 14.9 tok/s on a single RTX PRO 6000 and Qwen3.6-35B at 39.3 tok/s on an 8GB RTX 4060 laptop, claiming 2–4x Ollama throughput on consumer GPUs.
Compute remains the hard constraint: multiple operators argued inference capacity is tightening, not loosening—see saranormous on good AI companies being growth-limited by compute and Andrew Carr on self-hosting GPUs and still having more experiments than available capacity. This makes model efficiency, scheduling, and lower latency/tokens-per-dollar improvements strategically important.
Open-source training transparency is also scaling: Percy Liang announced Marin 535B-A23B has started training, targeting 18.75T tokens on 11× GB200 NVL72 over ~3 months, with the run kept open as usual.
Top tweets (by engagement)
DeepSeek launches V4-Flash-Vision-Exp — the clearest product release of the day, and likely the biggest practical shift for multimodal agents.
OpenAI cuts GPT-5.6 Sol pricing by >20% — meaningful pricing pressure at the frontier.
Codex reaches 20M active users; banked resets for users — notable product growth signal.
NVIDIA AVO hits 100% on ARC-AGI-3 public environments with Chollet’s caveat — impressive, but benchmark interpretation matters.
David Sacks on Harvey using open-source Kimi K3 for legal SOTA at lower cost — strong argument for why restrictions on open models would mostly hurt US application-layer companies.
AI Reddit Recap
/r/LocalLlama + /r/localLLM Recap
1. Qwen3.8 27B Local Agent Evaluations
Qwen3.8-27b has the highest level of “agency” I’ve ever seen in a local model (Activity: 1334): The post claims Qwen3.8-27B running locally on a single RTX 3090 with Unsloth Q4_K_S quantization, q8 KV cache, and 150k context performed unusually capable autonomous agent workflows: using Playwright plus existing SSO/session cookies to navigate university systems and retrieve a course schedule, and separately processing a social-media video via download, frame extraction, transcription with Whisper, and image enhancement. The image is a screenshot of the model reporting use of an Outlook/OWA Playwright profile, Microsoft “stay signed in,” and Duo browser-trust cookies to access school systems, making the technical significance less about raw model quality alone and more about local LLM tool-use agency plus high-risk credential/session handling. Comments were impressed but cautious: one user explicitly worried about giving an agent enough access to potentially perform destructive actions like withdrawing from university, while others framed it as evidence that advanced local agentic systems are already here but unevenly distributed. A commenter asked for implementation details behind the reported agentic behavior of Qwen3.8-27B, specifically the agent harness used—e.g. Claude Code, Hermes, or another framework—and how tools were exposed via MCP servers, browser tools, Python, filesystem access, etc. They also asked what inference backend served the model, such as llama.cpp, and how it was able to autonomously download video, extract frames, and install Whisper. There was technical concern about the reliability of the referenced quantization: one commenter noted surprise that “the quant is that good,” while mentioning reports of looping behavior at that quant. This suggests the model’s apparent agency may be sensitive to quant level and runtime behavior, especially for long-horizon tool use. A safety-oriented thread questioned giving local agents broad system access, with one commenter saying they would not trust agents like Sol or Fable with unrestricted permissions. The concern was not about local inference itself, but about autonomous agents with enough privileges to perform impactful real-world actions such as modifying accounts or workflows.
Qwen3.8-27B took a serious hit to knowledge vs 3.6 (Activity: 779): The post reports that Qwen3.8-27B / Qwen3-8-27B appears to regress vs Qwen3.6-27B / Qwen3-6-27B on offline, no-tool-call factual recall: the author’s private “mildly obscure” trivia/prepper benchmark showed failures across quantization levels and sampling settings, consistent with lower scores on Artificial Analysis’ Omniscience knowledge benchmark. The reported degradation is specifically about knowledge stored in weights and hallucination/fact recall under airgapped inference, not coding/tool-use; commenters note Qwen3.8 is stronger at tool calling, web search/fetch workflows, coding, and agentic behavior. Commenters broadly frame this as an intentional tradeoff: newer Qwen 3.x models may be optimized for coding/agentic tasks rather than being “mini Google” factual stores, with Gemma 4 suggested as a better fit for trivia/random-fact recall. One user confirmed regression on niche visual/history/geography tasks such as stamp or old-photo location identification when web tools are disabled, but considered the tradeoff acceptable given improved tool use. Several commenters frame Qwen3.8-27B as shifting away from memorized factual recall toward coding, tool use, and agentic workflows. One user testing a niche “knowledge” workload—stamp identification and historical/location inference from old photos—reported that with web search/fetch tools disabled, Qwen3.8 performs worse than Qwen 3.6, but becomes more useful when allowed to retrieve information externally. The perceived regression is described as an intentional tradeoff for a 27B model: reduce obscure memorized knowledge while preserving enough reasoning ability for problem solving and agents. Commenters suggest using models like Gemma for factual/trivia-heavy tasks, while reserving Qwen3.8 for coding/tool-calling scenarios where users report stronger performance. One technical speculation was that future models may separate base reasoning from domain knowledge via neural plugins/LoRA-like modules: e.g., adding Japanese-language capability or finance-domain expertise as attachable components rather than baking all knowledge into the base model. This was proposed as a way to keep base models smaller or more specialized while allowing opt-in domain expansion.
Qwen 3.8 27b - PI AGENT vs OPENCODE (Activity: 510): The author compares PI Agent vs Opencode using a local llama-server backend on an RTX 3090 with Qwen3.8-27B-Q4_K_M.gguf , ctx-size=100000 , flash-attn=on , n-gpu-layers=99 , DeepSeek-style reasoning, and a vision mmproj module. They report PI Agent producing better outputs, using fewer tokens, avoiding Opencode’s apparent 32k output-token ceiling/freezing behavior, and delaying context compression until ~ 90k tokens vs Opencode starting around ~ 67k when total context is 100k ; they also recommend enabling vision so the model can visually assess generated outputs, with CPU/RAM offload acceptable for screenshot evaluation latency ( ~3s vs ~0.3s GPU). The test was inspired by a prior LocalLLaMA post about generating a bouncing-ball animation: reddit.com/r/LocalLLaMA/comments/1j7r47l/.... Commenters questioned whether a one-shot HTML/animation task is a meaningful harness comparison and suggested multi-step tool-heavy workflows instead. Another user reported PI + local Qwen3.8-27B felt competitive with Claude Code on a roughly one-hour aurora-prediction app build, though both models judged Claude’s initial result slightly better before PI iterated. A commenter argues that one-shot HTML generation is not a meaningful benchmark for comparing PI Agent vs OpenCode; they suggest using multi-step tasks with extensive tool calls to evaluate the harnesses’ planning, editing, and recovery behavior. One user reports a subjective head-to-head between local Qwen3.8-27B running in PI and Claude Code on building an aurora predictor app. They felt runtime was similar; both agents judged Claude’s first result slightly better, but after asking PI/Qwen to upgrade its version, the user preferred Qwen’s presentation. The resulting app reportedly integrated multiple satellite instruments and provided 30–60 minute aurora warnings. Another commenter suggests adding the DeepSeek harness to the comparison, implying the evaluation should cover more agent runtimes than just PI Agent and OpenCode.
2. DeepSeek V4 Flash Benchmarks and Serving
DeepSeek-V4-Flash-Vision-Exp (Activity: 722): The image is a technical benchmark table for DeepSeek-V4-Flash-Vision-Exp (image), comparing it against DeepSeek V4-Flash-0731 and Opus-4.8 on text-agent and multimodal-agent evaluations. It shows broad gains over the prior DeepSeek Flash release, including 83.9 on Terminal Bench 2.1, 75.9 on Toolathlon-Verified, and 64.3 on Chartography, while Opus-4.8 still leads many text-heavy benchmarks; Vision-Exp appears more competitive on multimodal tasks such as Agents’ Last Exam and ZeroBench. The main technical reaction was that the reported DeepSWE improvement of roughly +4 points over 0731 is considered unusually large. Other comments were mostly hype or tribal reactions rather than substantive analysis. DeepSeek’s announcement says DeepSeek-V4-Flash-Vision-Exp is live via the DeepSeek API with model='deepseek-v4-flash-vision-exp' , matching DeepSeek-V4-Flash text capabilities while adding multimodal input. The model supports Chat Completions, Messages, and Responses APIs, with mixed text+image inputs via base64, external URLs, or the Files API; images are billed as up to 384 tokens each at V4-Flash pricing. Docs: vision guide. Several comments focused on benchmark movement: one noted DeepSWE reportedly improved by 4 points from 0731 to Vision-Exp, while the announcement claims a “major leap” on multimodal agent benchmarks, bringing performance close to Opus-4.8. The technical implication discussed is that Vision-Exp may retain V4-Flash’s agent/reasoning/world-knowledge text performance while substantially improving visual-agent workflows. DeepSeek also launched a Files API for image reuse: users can upload an image once, reference it by file_id , and avoid resending image payloads across requests, reducing bandwidth overhead. One commenter asked whether the model weights would be open and noted they could not yet find them on Hugging Face, implying that availability appears API-only at the time of discussion. Files API docs: files_api.
The boring way to run Deepseek V4 Flash-0731 130-150 tks - 16x5060ti 16GB over 2 PLX88096 switches (Activity: 621): The image is a terminal GPU-monitoring dashboard validating the post’s unusual 16× RTX 5060 Ti 16GB inference rig: all GPUs are visible, nearly full at roughly 15.2–15.7 GiB / 15.9 GiB VRAM, and assigned to vLLM worker processes for DeepSeek V4 Flash-0731. The setup uses two Broadcom/PLX PEX88096 PCIe switch islands with patched NVIDIA 610.43.02-p2p , Resizable BAR/BAR1 set to 16 GiB per GPU, and custom all-reduce/DSpark pipeline parallelism; reported throughput is about 100–150 tok/s single-user generation depending on TP/PP layout, with concurrency scaling up to 727 output tok/s aggregate for TP4/PP4 at 16 users. The image also shows the tradeoff/oddity of the build: the GPUs appear connected at PCIe Gen1 x8 and are mostly idle at the captured moment despite high VRAM residency, implying the screenshot is more a topology/memory residency proof than a live utilization benchmark. Commenters were less focused on the benchmark table and more on the physical absurdity of the build, asking for “a photo of the setup” and calling it a “mad setup.” One notable skeptical/funny technical reaction was that “a little vibe coding” likely hides substantial custom distributed-inference work.
The source text above remains the property of its publisher and is reproduced for commentary.